We trained a decoder-only GPT [1] written from scratch, with no nn.Transformer, no F.scaled_dot_product_attention and no HuggingFace model code, to a final cross-entropy of 2.14 on TinyStories [2], in 20,000 steps on a single Apple Silicon laptop. The shipped checkpoint is 5,263,848 parameters, configured as 6 pre-LN blocks [3], 8 heads, a 256-dimensional residual stream, a 64-token context, and a 1,000-token byte-level BPE [4][1] vocabulary trained on the corpus itself.
The loss is not a result. It is a receipt, evidence that every stage of the pipeline, from tokenizer and cache through loader, model, loss and sampler, is wired correctly end to end, which was the entire goal. The run consumed
Reading note. The argument is that the naive implementation makes the mechanism visible, and that the expensive failures were all silent.
Why It Matters
Reading the transformer paper [5] and reading a reference implementation both leave the same gap. You can follow every line and still not know which lines are load-bearing. Typing it out closes that gap by force. Every constant omitted and every shape gotten wrong produces either a crash or, worse, a model that trains to nothing while looking fine.
Technical Details
Attention Is Three Linear Maps and a Mask
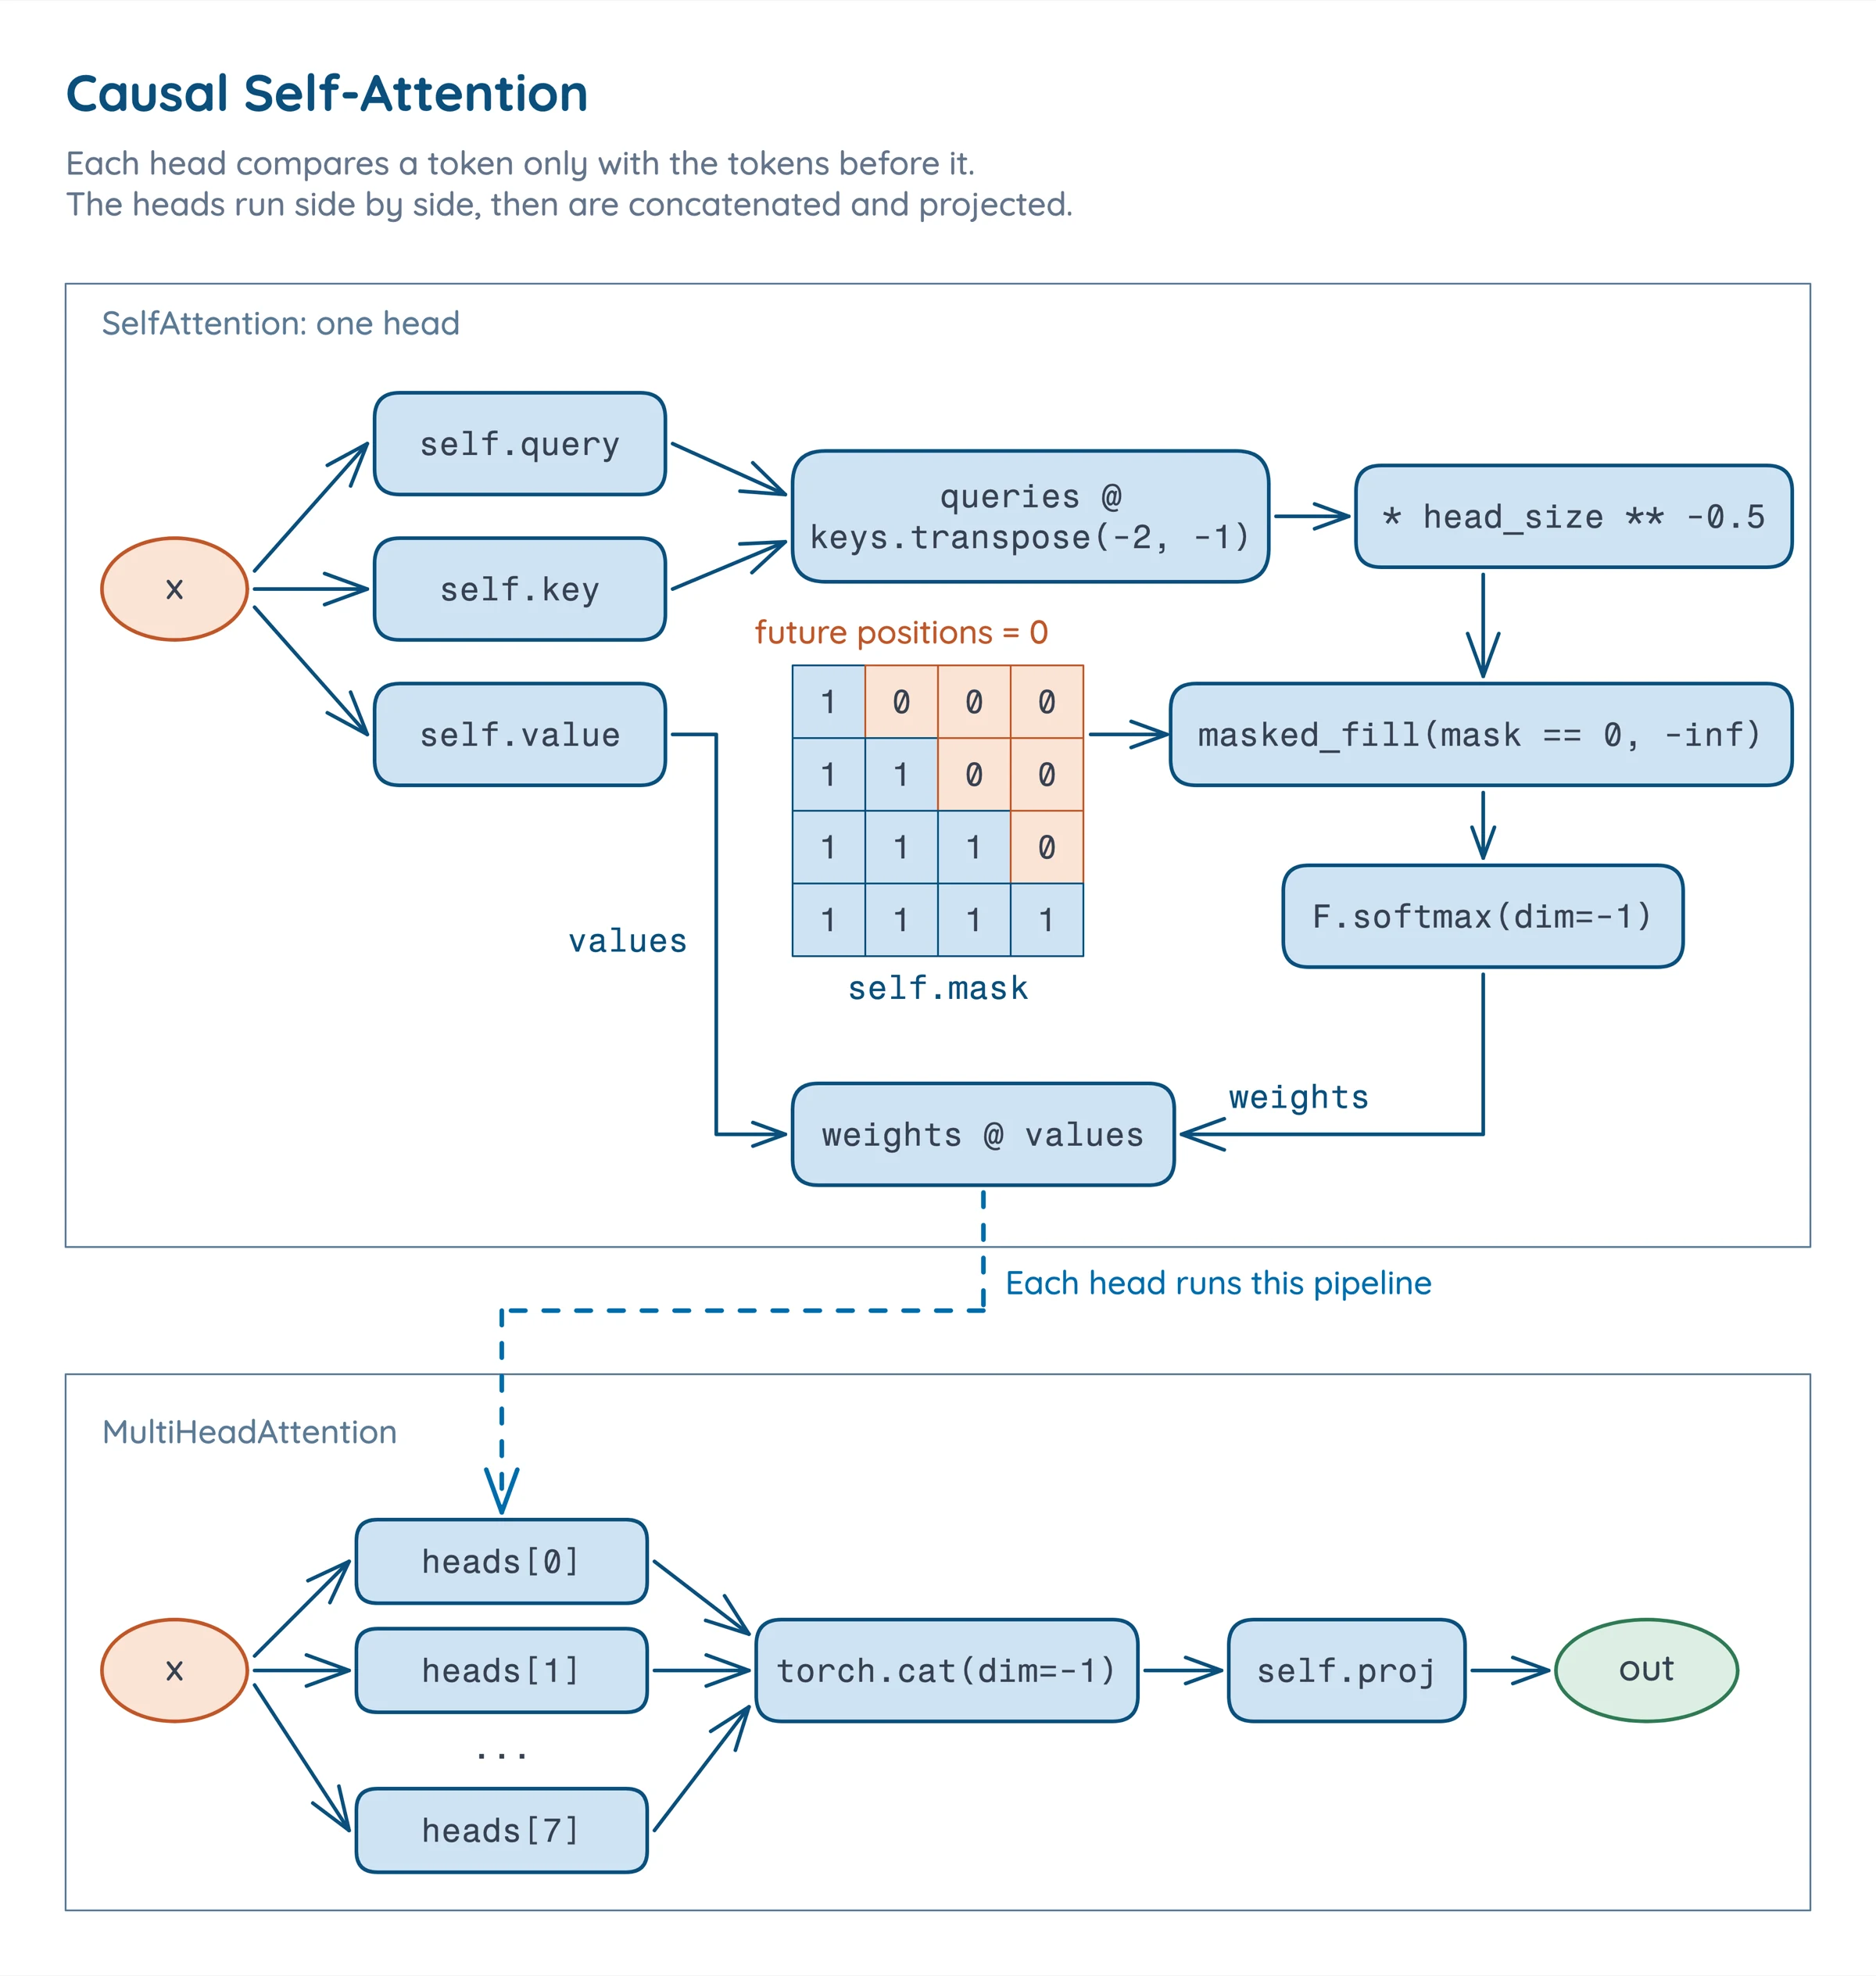
The single-head forward pass in full.
keys, queries, values = self.key(x), self.query(x), self.value(x) |
Four operations. A token's query is a question, every other token's key is an advertisement, the dot product scores the match, and the value is what actually gets moved. The causal mask is not a deep architectural property. It is a lower-triangular matrix of ones the size of the context, built with torch.tril and registered as a buffer, plus a masked_fill.
The Scale Factor Is Not a Detail
Multiplying the scores by one over the square root of the head size looks like a detail, and it decides whether the model trains.
Take a query
and the logits entering the softmax have standard deviation
Without the scale, logits grow with head size, the softmax collapses toward one-hot, and the gradient through it vanishes, because
At
The Residual Stream Is the Actual Abstraction
x = x + self.attention(self.layer_norm1(x)) |
Two x + ... lines, and they are the reason depth works at all. Each block proposes an edit to a running representation rather than replacing it. Normalization goes before the sublayer (pre-LN), so the residual path from input to output is unnormalized and gradients reach layer 0 intact [3].
Once the residual stream reads as a shared bus that every layer writes to and reads from [7], the later literature of logit lens [8], activation patching [9] and circuits [7] stops being exotic and starts being the obvious next question. That framing is what sent this project toward induction heads [10] next.
Architecture
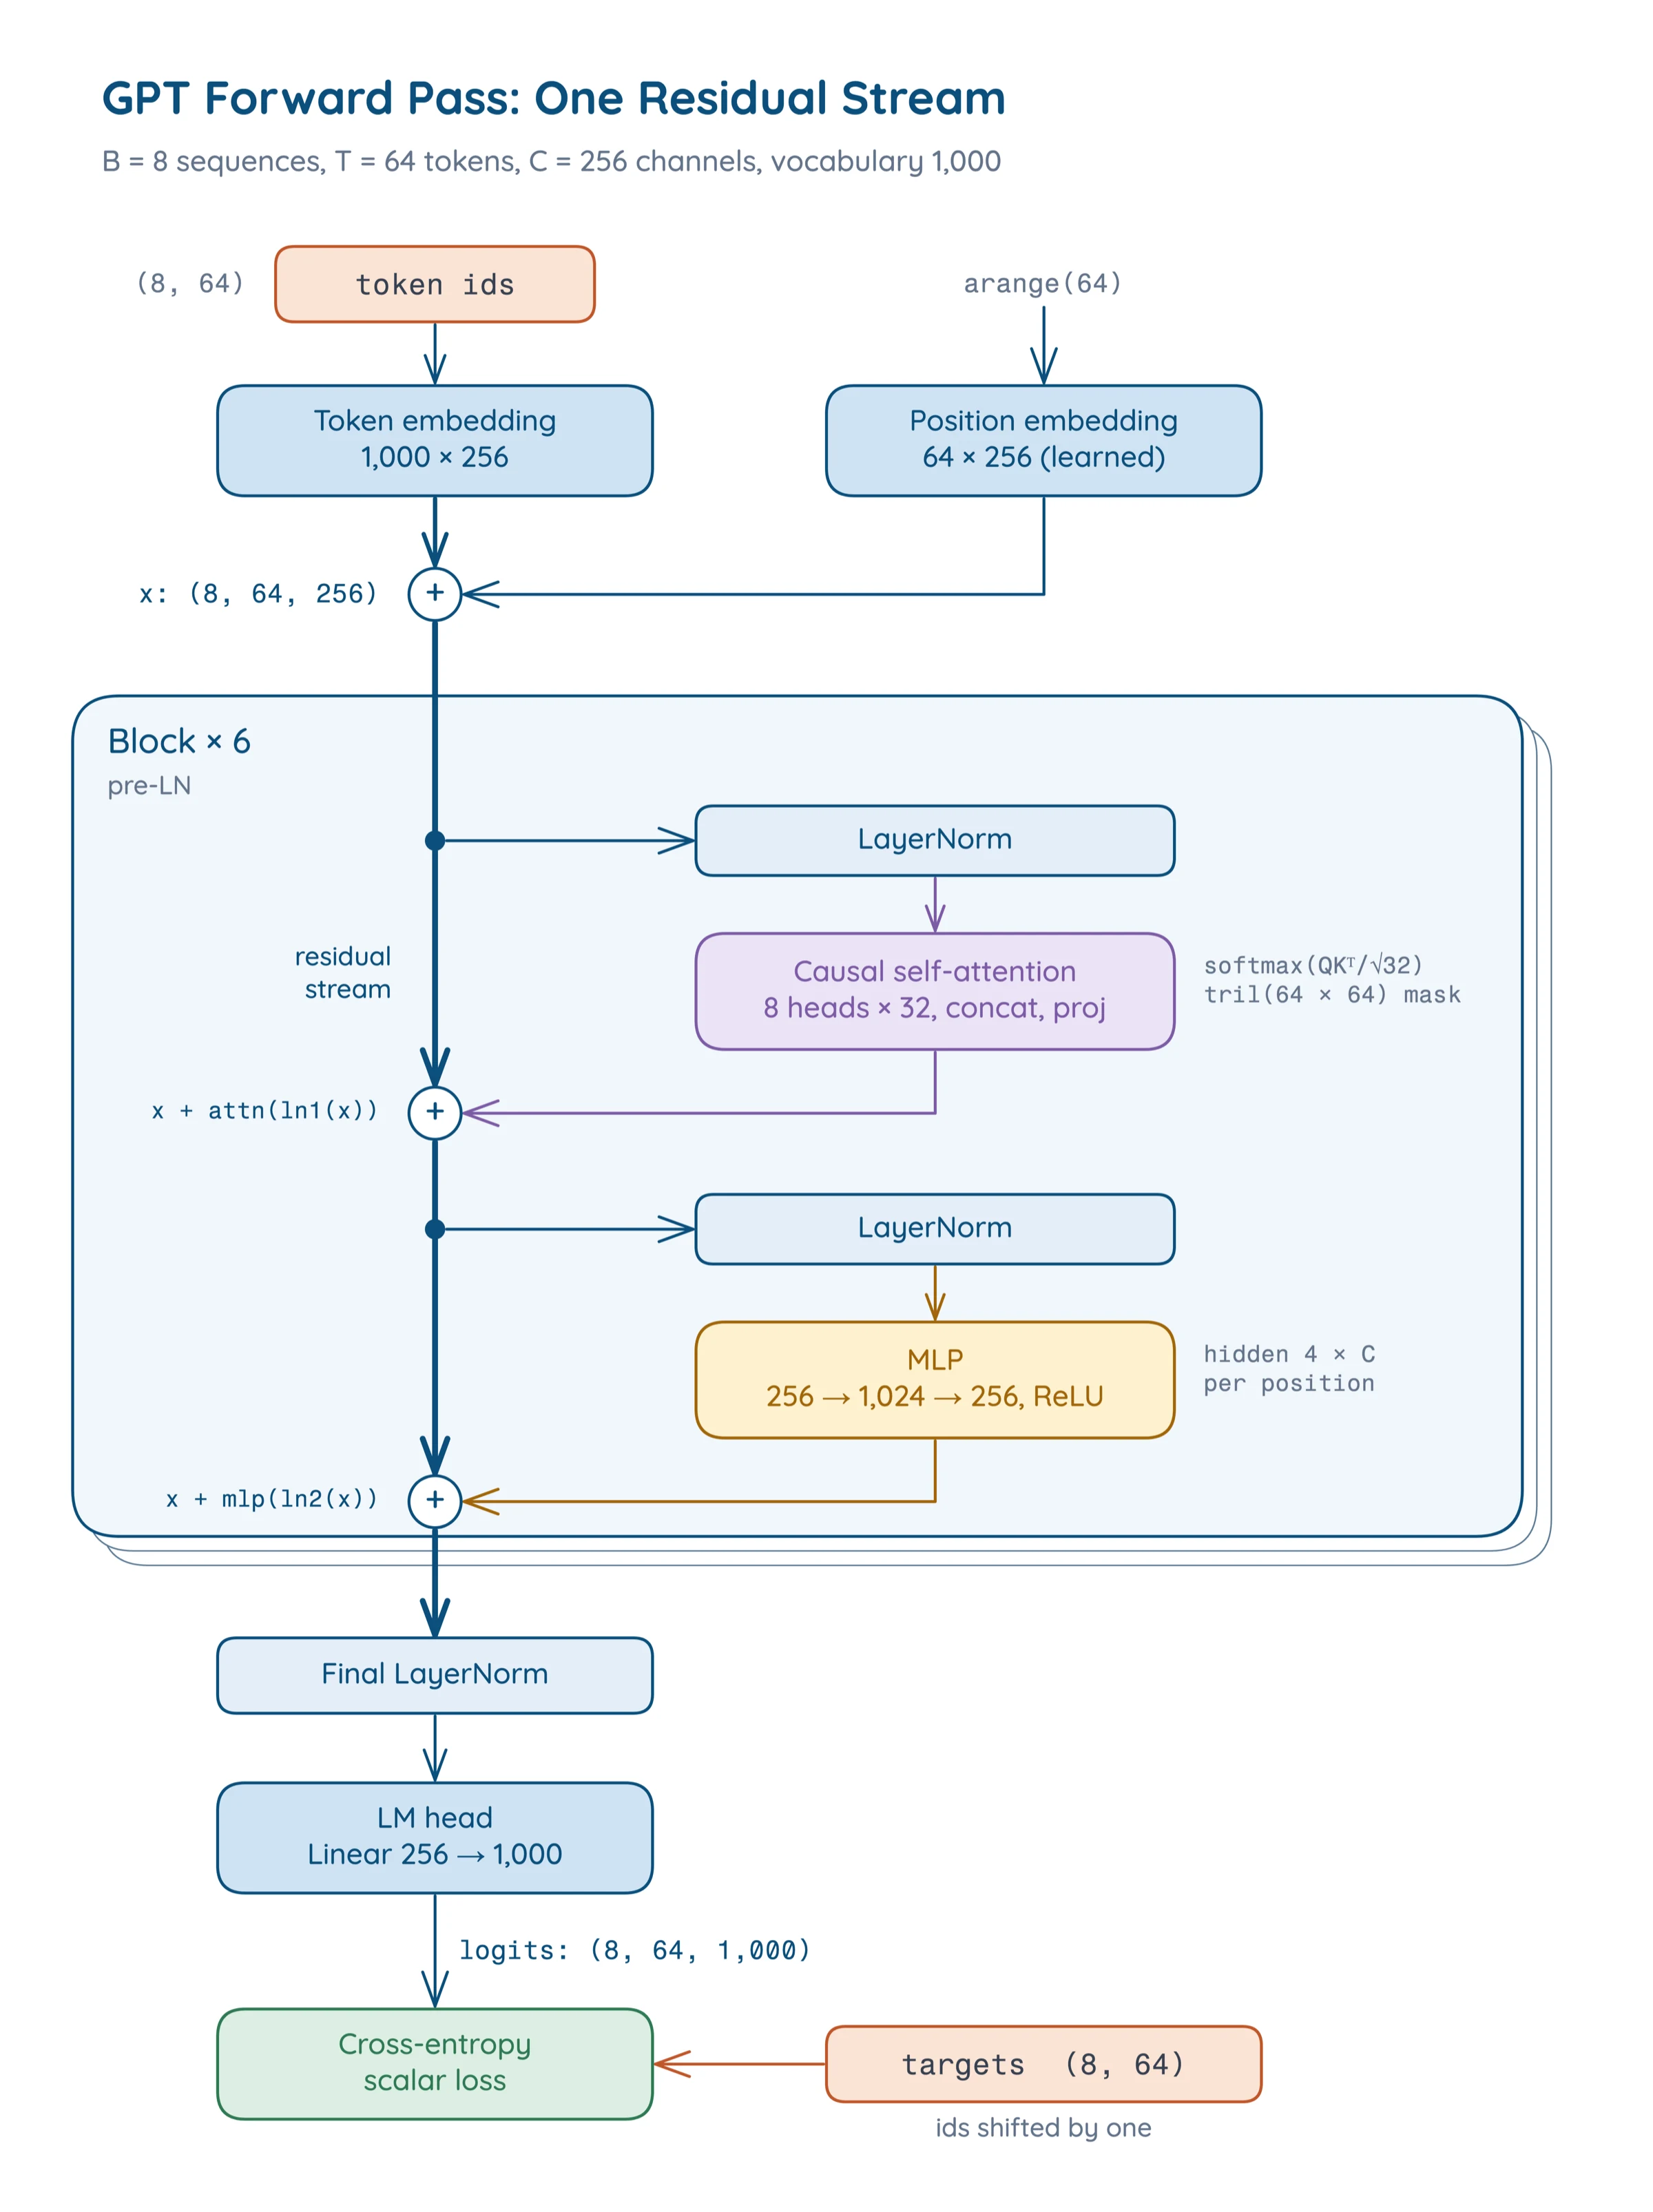
Full Architecture, as Configured in the Shipped Checkpoint
| Component | Value |
|---|---|
| Blocks | 6 |
| Attention heads | 8 |
| Residual width | 256 |
| Head size | 32 (residual width / heads) |
| Context | 64 |
| Vocabulary | 1,000 (byte-level BPE) |
| MLP | |
| Position encoding | Learned embeddings |
| Normalization | Pre-LN, two LayerNorms [6] per block |
| Parameters | 5,263,848 |
The parameter count breaks down as 272,384 in the embeddings (256,000 token + 16,384 positional), 4,733,952 across the six blocks, 512 in the final LayerNorm, and 257,000 in the unembedding. The causal masks are registered buffers and are not counted, which is why the usual count over the model's parameters excludes the 196,608 mask entries in the state dict.
Implementation
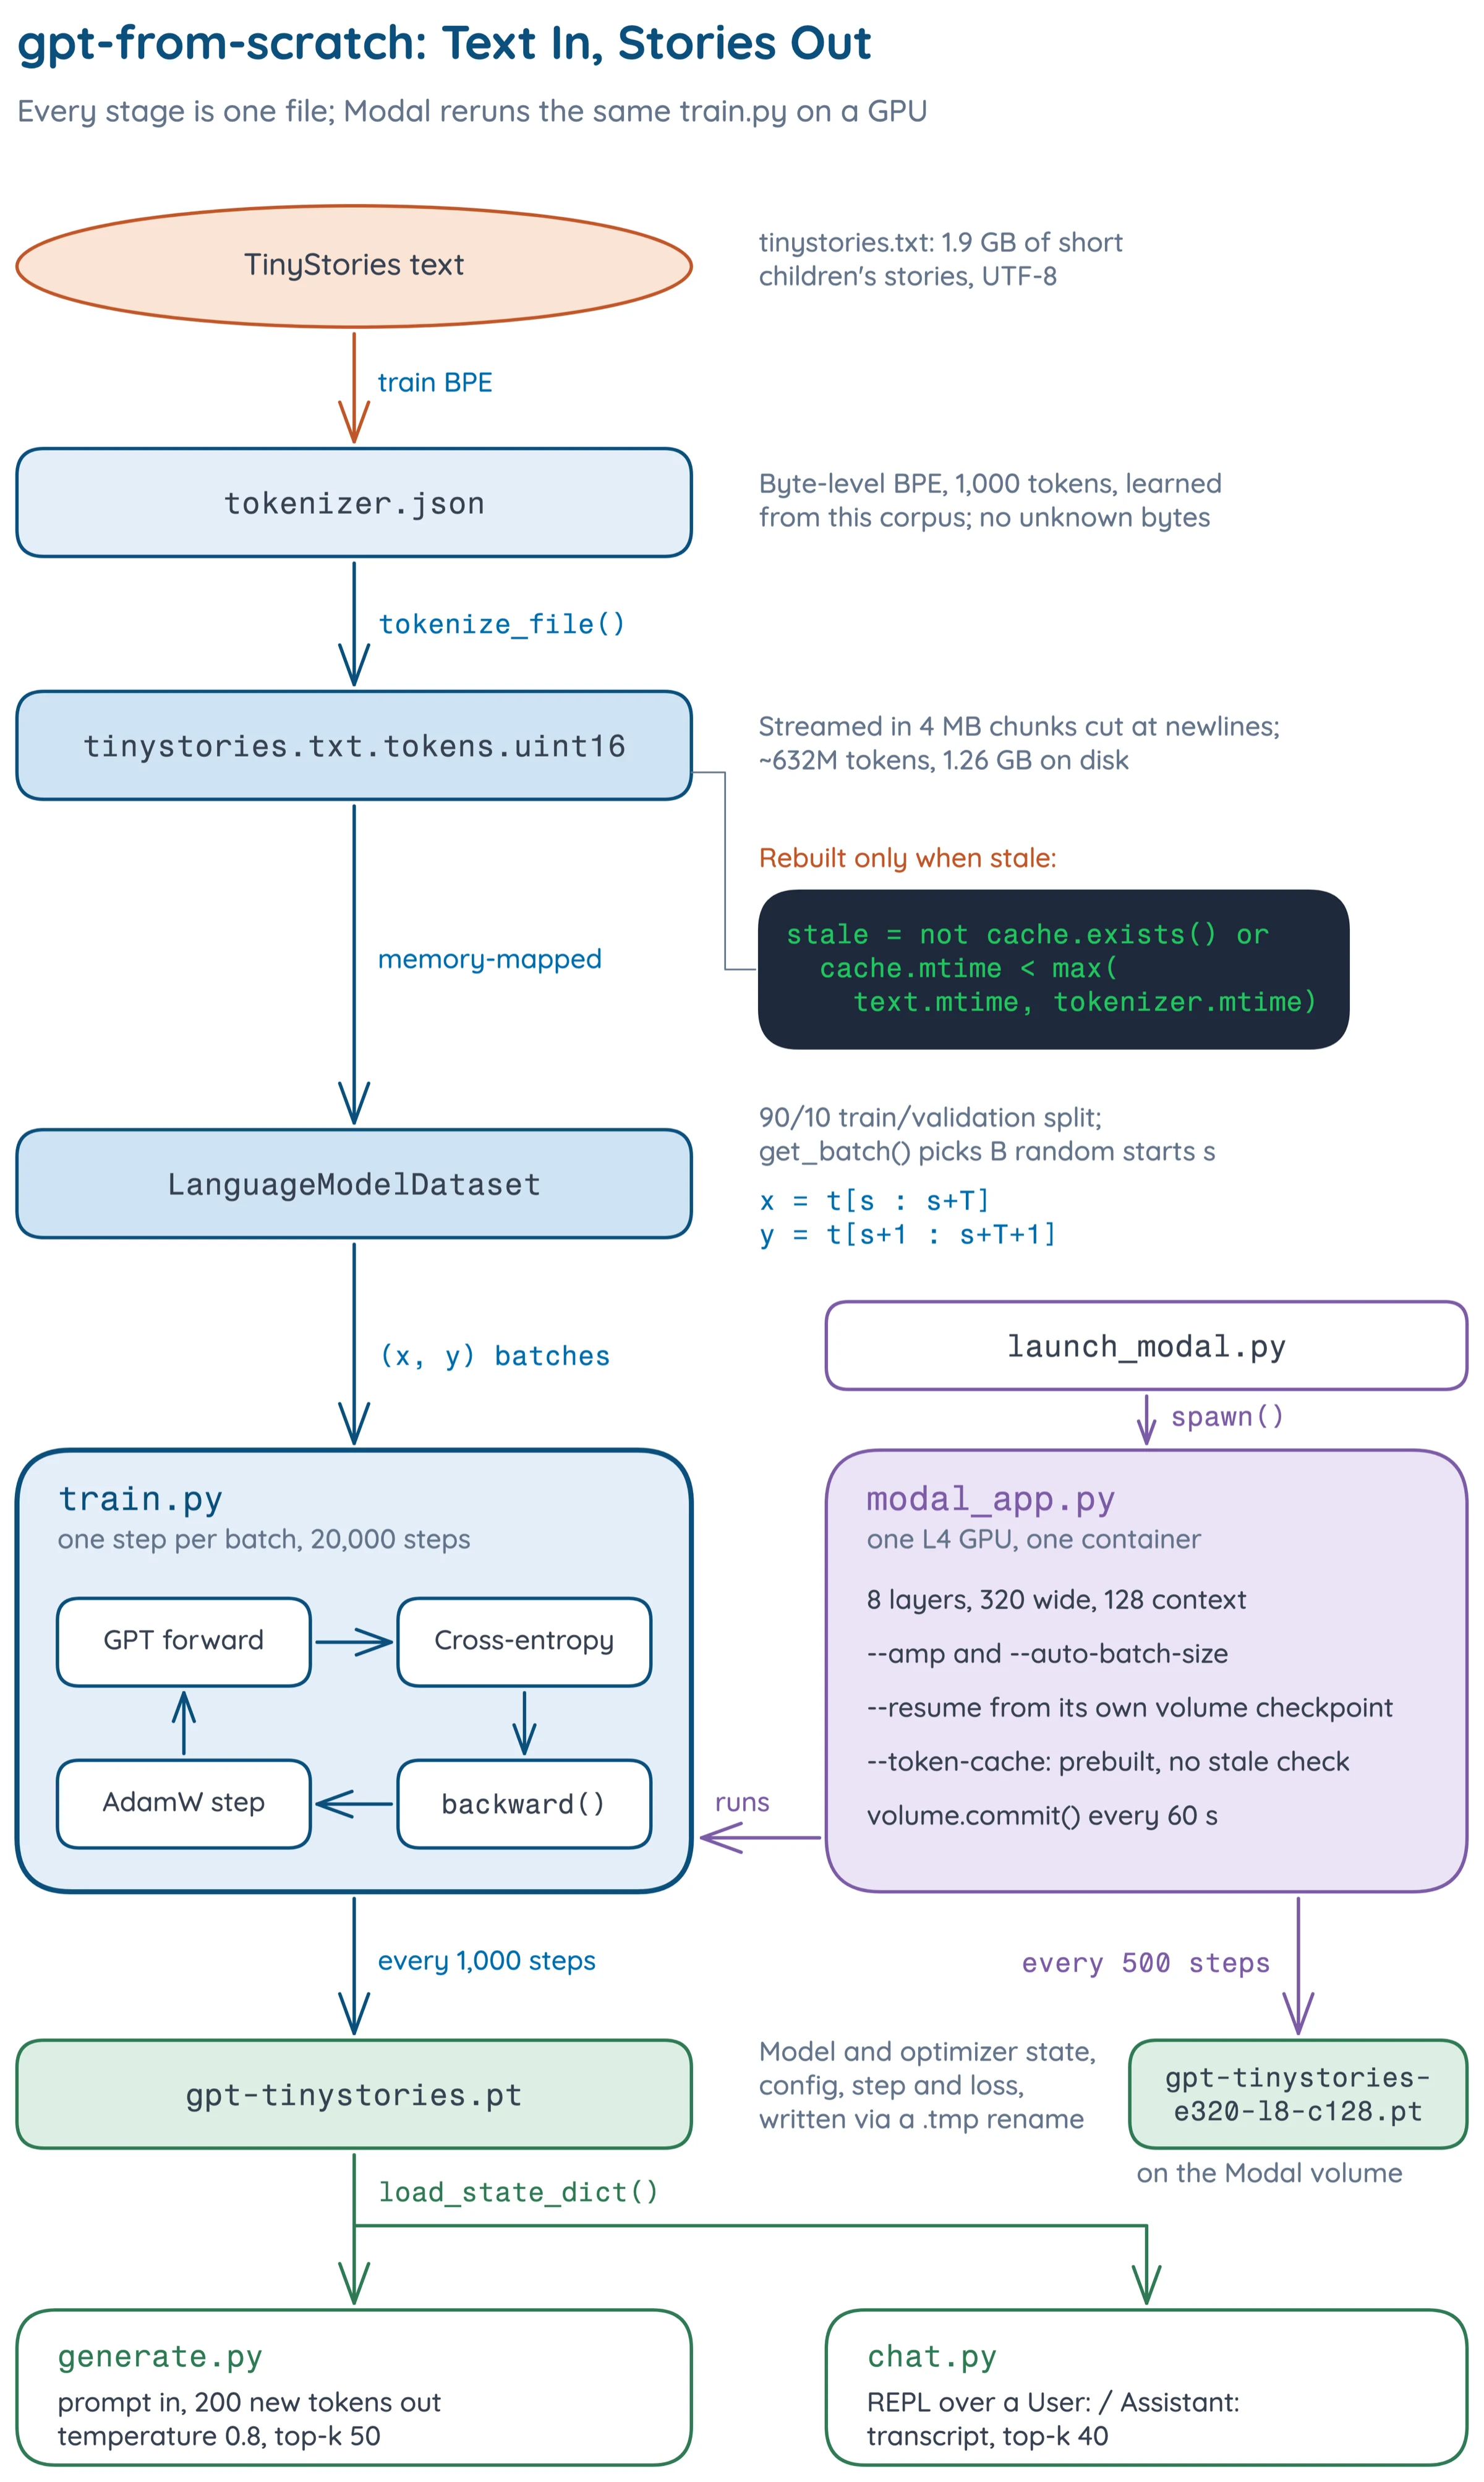
The project covers the whole path: a tokenizer, a streaming data pipeline, the model, a training loop, a sampler, a chat REPL, and a harness for the GPU runs on Modal.
Multi-Head, Implemented the Slow Way on Purpose
self.heads = nn.ModuleList([SelfAttention(...) for _ in range(num_heads)]) |
Production implementations fold all heads into one batched matmul. This one keeps them as independent modules and concatenates. That is measurably slower, and we kept it. Heads genuinely are independent subspaces, and writing them as separate objects makes that structural fact impossible to forget. Fusing is an optimization, not a concept, and the independence is exactly the property that later interpretability work depends on. The induction-circuit project scores heads individually, which only means something because they are individual.
At 3.8M–5.3M parameters on a laptop the trade is free. At any serious scale it is not, and the right move is to fuse and keep a slow reference implementation for testing against.
The Tokenizer and the Data Pipeline
The least interesting part took the most iterations.
Byte-level BPE [4][1] with a ByteLevel pre-tokenizer and decoder means no unknown tokens are possible, since every byte sequence encodes. That sounds like a footnote and is what makes the model robust to whatever the corpus contains. The vocabulary is trained on the corpus itself rather than borrowed, which at 1,000 merges over children's stories gives a tokenizer specialized to exactly this distribution.
Streaming Tokenization and Cache Invalidation
The corpus is 1.9 GB of text and stopped fitting comfortably in memory. Tokenization became a streaming pass that writes a uint16 token cache to disk, invalidated by comparing modification times against both the source text and the tokenizer.
cache_is_stale = not token_cache.exists() or token_cache.stat().st_mtime_ns < max( |
uint16 because a 1,000-token vocabulary fits in 16 bits, which halves the cache versus int32. The resulting cache is 1.26 GB, or roughly 632M tokens.
The staleness check exists because the tokenizer was retrained once, and an hour of training then ran against tokens from the previous vocabulary, a corruption that produces no error, just a model learning a scrambled language.
Training, and How Much Data the Run Actually Saw
AdamW [11] at its default weight decay of 0.01, learning rate
No learning-rate schedule, no warmup, no gradient clipping. At this scale none were necessary, and leaving them out kept the loop readable. At larger scale each is the next thing to add.
The number worth stating plainly is the token budget.
against a cache of roughly 632M. The run therefore saw about 1.6% of the corpus, once. The final loss of 2.14 is a number from a model that is data-starved by design, and the correct reading of it is "the pipeline learns" rather than "the model is good." Anyone comparing it to a published TinyStories loss is comparing against a different experiment.
Sampling
Greedy decoding on a model this size produces loops almost immediately [12]. Temperature and top-
logits = logits[:, -1, :] / temperature |
The thing worth internalizing is that the model is a distribution, not a speaker. Every "the model said X" is really "this decoding strategy, at this temperature, said X." Two of the qualitative judgments we made early about model quality turned out to be judgments about decoding.
Scaling to a GPU, and What It Bought
Once the laptop run worked, training moved to a Modal L4 with a larger configuration of 8 layers, 320-dimensional residual, 128-token context, mixed precision, and an auto batch-size search that doubles the batch until CUDA runs out of memory.
The observation worth recording is how little of that work was model code. The same training script runs unchanged on CPU, Apple's MPS backend and CUDA, picking the device automatically. What the GPU run required was infrastructure.
The Supervising Loop
The GPU run needed three things: a persistent volume so a preempted container does not lose the checkpoint, a resume path that points at the same checkpoint file the run writes to, and a supervising loop that commits the volume every 60 seconds.
while True: |
Six hours of GPU time is worth nothing if the container dies at hour five with the checkpoint in a tmpfs.
The model itself is 182 lines. The tokenizer, data pipeline, training loop, sampler, chat REPL, and Modal harness together are roughly four times that, and that is where all of the bugs were. The transformer was the easy half.
Problems
| Problem | Symptom | Cause |
|---|---|---|
| Stale token cache | Model trains, output is gibberish, loss looks plausible | Tokenizer retrained without invalidating the cached token file |
| Dataset target alignment | Off-by-one, loss plateaus higher than expected | Dataset pre-shifts targets; the loss shifts them again |
Both are silent. Neither raises. Both are the same category, a pipeline that is internally consistent and describing the wrong thing. That category is, we now believe, the dominant failure mode in small-scale ML work, and it is why the receipt matters more than the number on it.
Results
Had we reported only the final loss, this post would have described a trained model. The accurate version is that it describes a validated pipeline with a model attached that has seen 1.6% of its corpus once.
- The naive version is the point. Every optimization skipped is a concept left visible. Unfused multi-head attention costs throughput and buys understanding, and at this scale that trade is free.
- The scale factor and the mask are not details.
is the difference between a model that trains and one that silently does not, and the failure has no error message. - Most of the code is not the model. 182 lines of model against roughly four times that in everything else, and the bugs were all in the everything else.
- Silent correctness bugs dominate. Nothing in this project crashed in an informative way. Both expensive bugs produced a running system quietly learning the wrong function.
- The loss number is not comparable to anything. One pass over 1.6% of the data is not a training run anyone should benchmark against.
References
- Alec Radford, Jeffrey Wu, Rewon Child, et al. Language Models are Unsupervised Multitask Learners. OpenAI technical report, 2019. link
- Ronen Eldan, Yuanzhi Li. TinyStories: How Small Can Language Models Be and Still Speak Coherent English? arXiv preprint, 2023. arXiv:2305.07759
- Ruibin Xiong, Yunchang Yang, Di He, et al. On Layer Normalization in the Transformer Architecture. ICML, 2020. arXiv:2002.04745
- Rico Sennrich, Barry Haddow, Alexandra Birch. Neural Machine Translation of Rare Words with Subword Units. ACL, 2016. arXiv:1508.07909
- Ashish Vaswani, Noam Shazeer, Niki Parmar, et al. Attention Is All You Need. NeurIPS, 2017. arXiv:1706.03762
- Jimmy Lei Ba, Jamie Ryan Kiros, Geoffrey E. Hinton. Layer Normalization. arXiv preprint, 2016. arXiv:1607.06450
- Nelson Elhage, Neel Nanda, Catherine Olsson, et al. A Mathematical Framework for Transformer Circuits. Transformer Circuits Thread, 2021. link
- nostalgebraist. interpreting GPT: the logit lens. LessWrong, 2020. link
- Stefan Heimersheim, Neel Nanda. How to use and interpret activation patching. arXiv preprint, 2024. arXiv:2404.15255
- Catherine Olsson, Nelson Elhage, Neel Nanda, et al. In-context Learning and Induction Heads. Transformer Circuits Thread, 2022. arXiv:2209.11895
- Ilya Loshchilov, Frank Hutter. Decoupled Weight Decay Regularization. ICLR, 2019. arXiv:1711.05101
- Ari Holtzman, Jan Buys, Li Du, et al. The Curious Case of Neural Text Degeneration. ICLR, 2020. arXiv:1904.09751
- Angela Fan, Mike Lewis, Yann Dauphin. Hierarchical Neural Story Generation. ACL, 2018. link