We score all 144 attention heads of GPT-2 small on the induction diagonal and recover the five heads the literature names [1]. They are L5H5 (0.925), L6H9 (0.915), L7H10 (0.905), L5H1 (0.902), and L7H2 (0.820). The sixth-ranked head scores 0.529. That gap of 0.290 is what makes "the induction heads" a set rather than a cutoff someone chose.
The measurement is one cached forward pass over eight sequences of 101 tokens, and it runs in under a minute on an M4 Pro laptop. The model is GPT-2 small (124M) [2] via TransformerLens [3].
Reading note. The argument is the gap and what it does not license. The configuration details, the TransformerLens processing notes, and the experiment plan are self-contained. Skip to Conclusions if you only want the claim and its limits.
Why It Matters
Show a language model
This is experiment 01 of six, and it is the weakest kind of evidence in the plan it opens. An induction score is a correlation between a head's attention pattern and a behavior. It cannot separate a head that performs in-context copying from a head that attends to the right position for some unrelated reason while another component does the copying. We report these scores as a validated instrument reading, not as a circuit claim. The four experiments that would make it a circuit claim are specified below and have not been run.
Technical Details
The Behavior
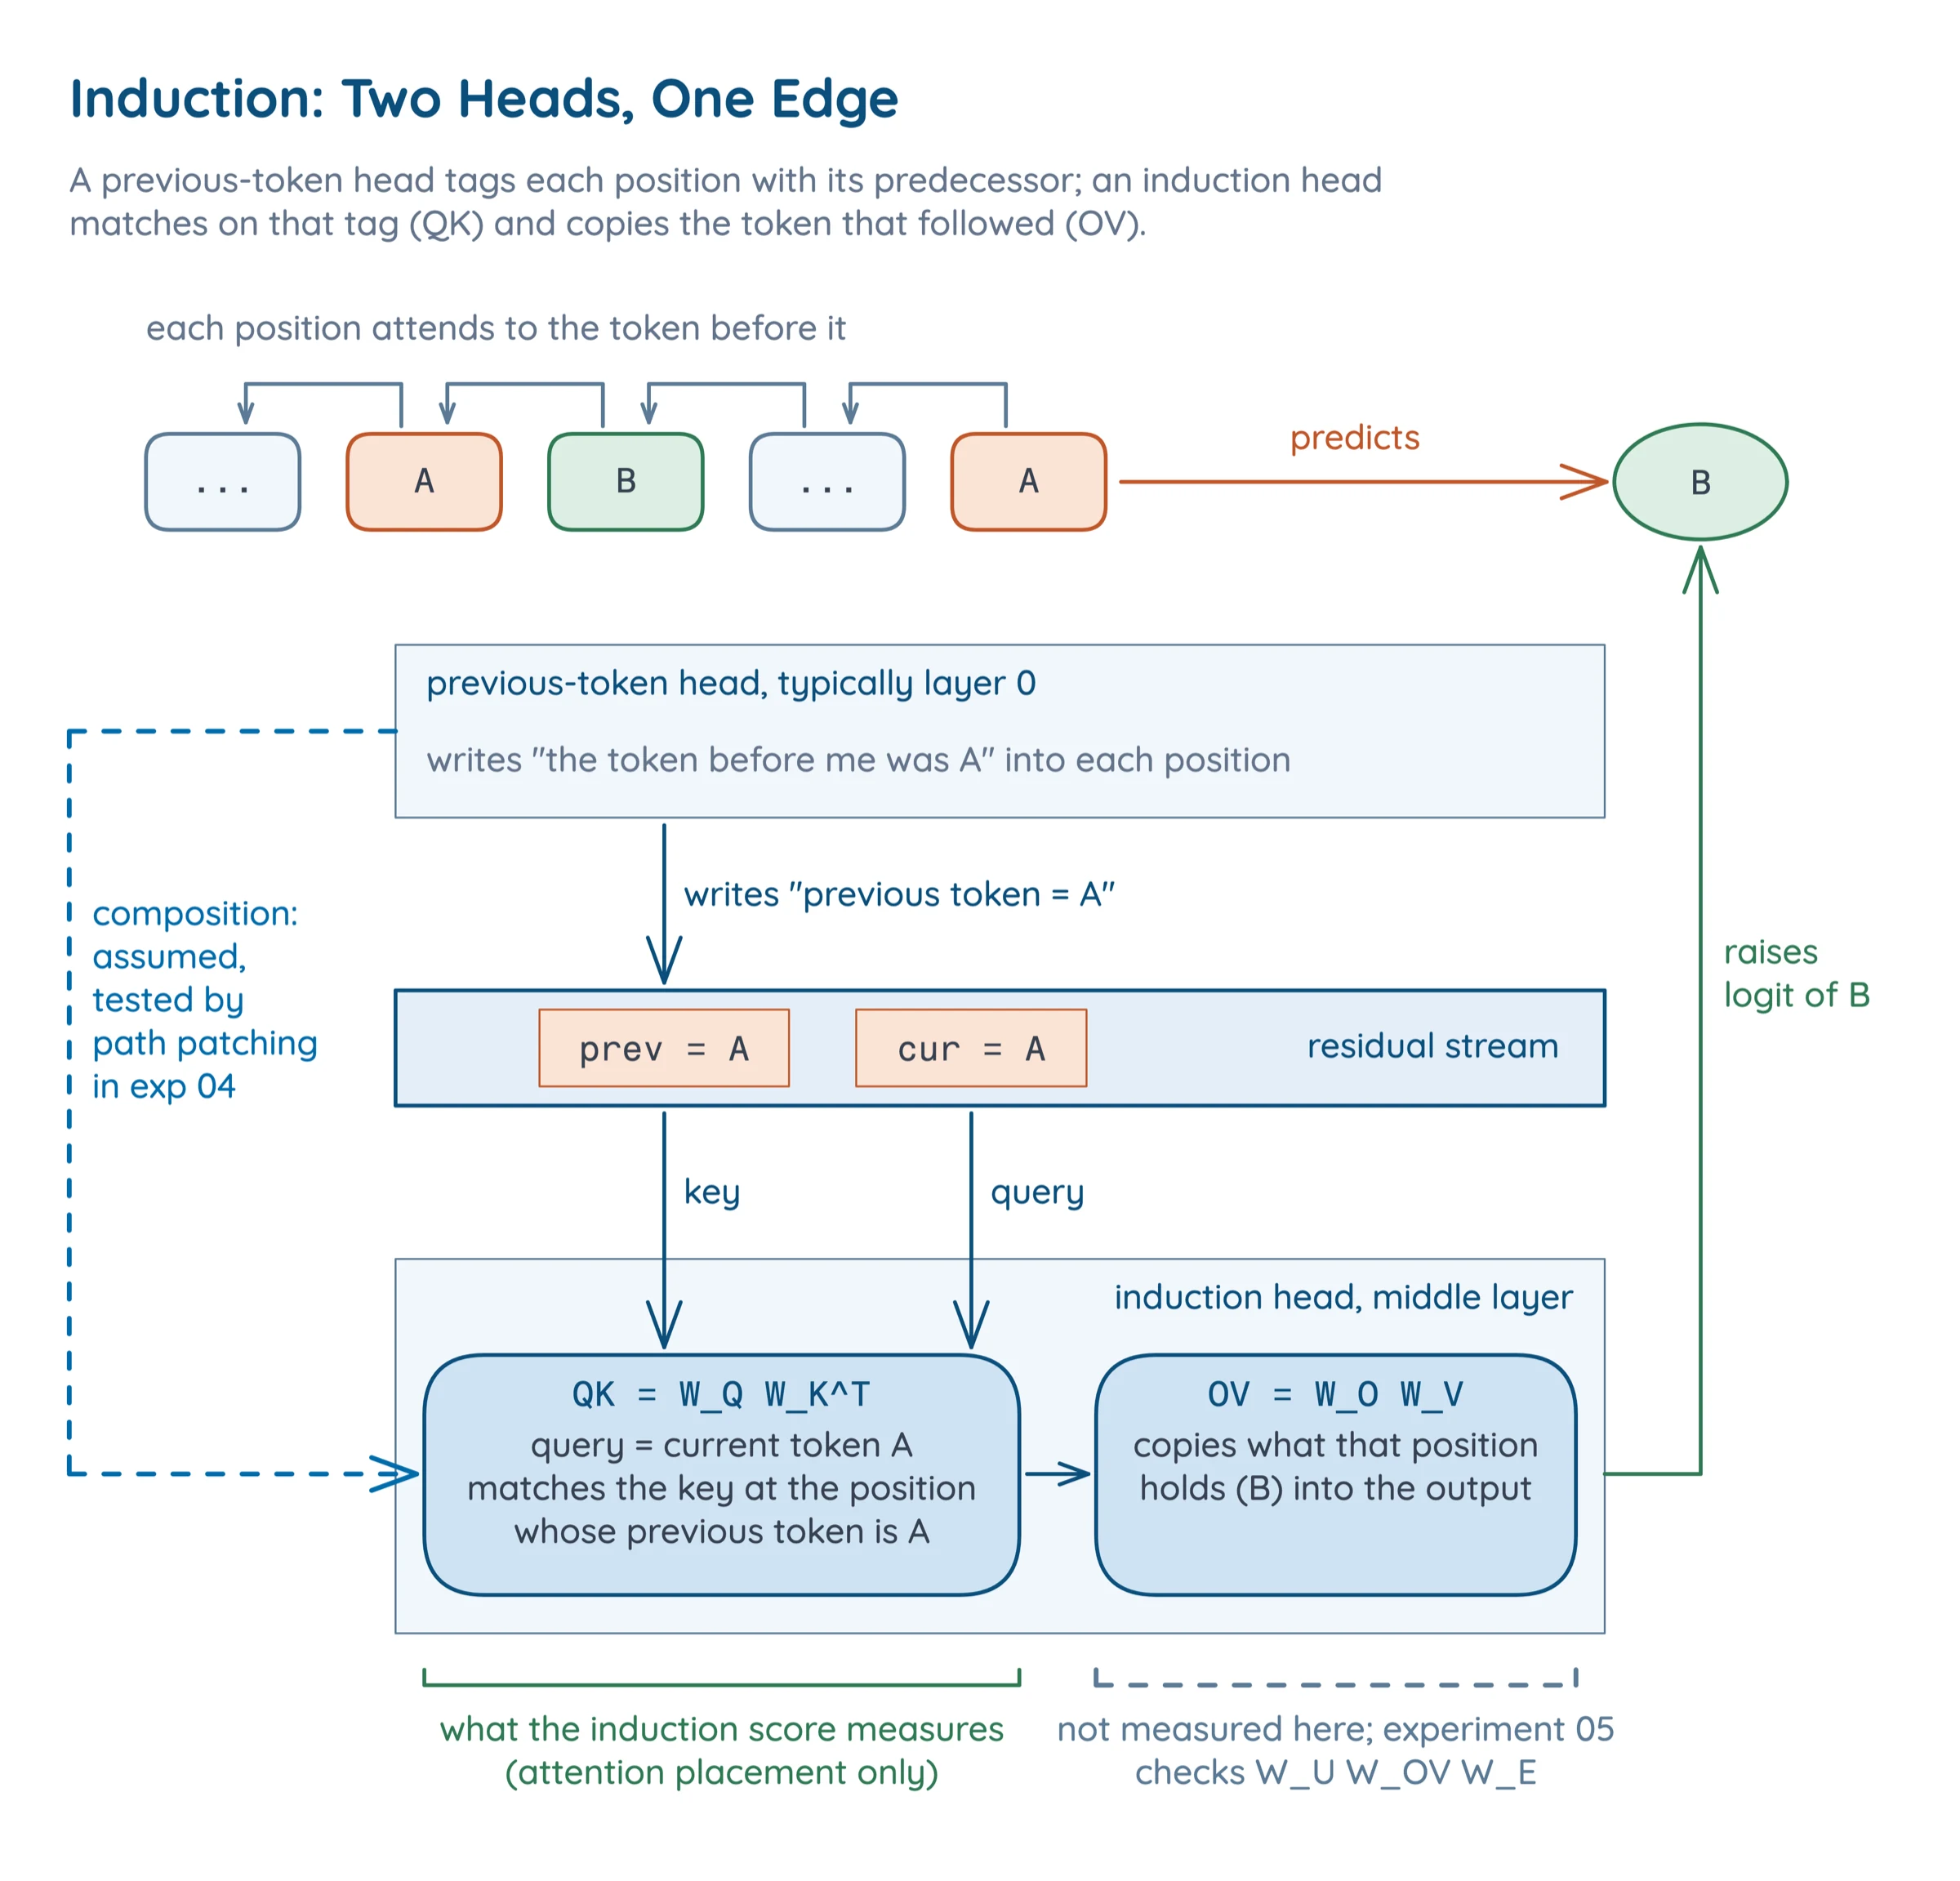
The claimed implementation is two heads composed across layers [5].
- A previous-token head, typically in layer 0, writes "the token before me was
" into each position's residual stream. - An induction head, in a middle layer, queries for that signature. It finds the position whose previous token matches the current token, and its OV circuit copies what that position holds into the output.
Two heads and one edge between them. Every part of that claim is separately testable, and this experiment tests the weakest part of it, whether heads exist whose attention goes where the story says it should.
QK and OV, Where a Head Attends versus What It Moves
An attention head factors into two circuits that can be analyzed separately [5], and the separation is what makes "which head does what" a tractable question.
The QK circuit decides where to attend. It is the bilinear form
The OV circuit decides what gets moved once a position is attended to. It is
The split matters for this project because an induction score only measures the QK side. It says the head looks in the right place. It says nothing about whether the OV side moves anything useful, which is why experiment 05 examines
Why a Repeated Random Sequence
Measuring induction on natural text conflates the thing we want with three things we don't. A head that attends "correctly" on English may be exploiting grammar, semantics, or a memorized n-gram rather than repeat structure, and the attention pattern looks the same in all four cases.
The input removes every alternative by construction. The test on repeated random tokens follows Olsson et al. [4].
rand = torch.randint(0, vocab, (batch, seq_len), generator=g) |
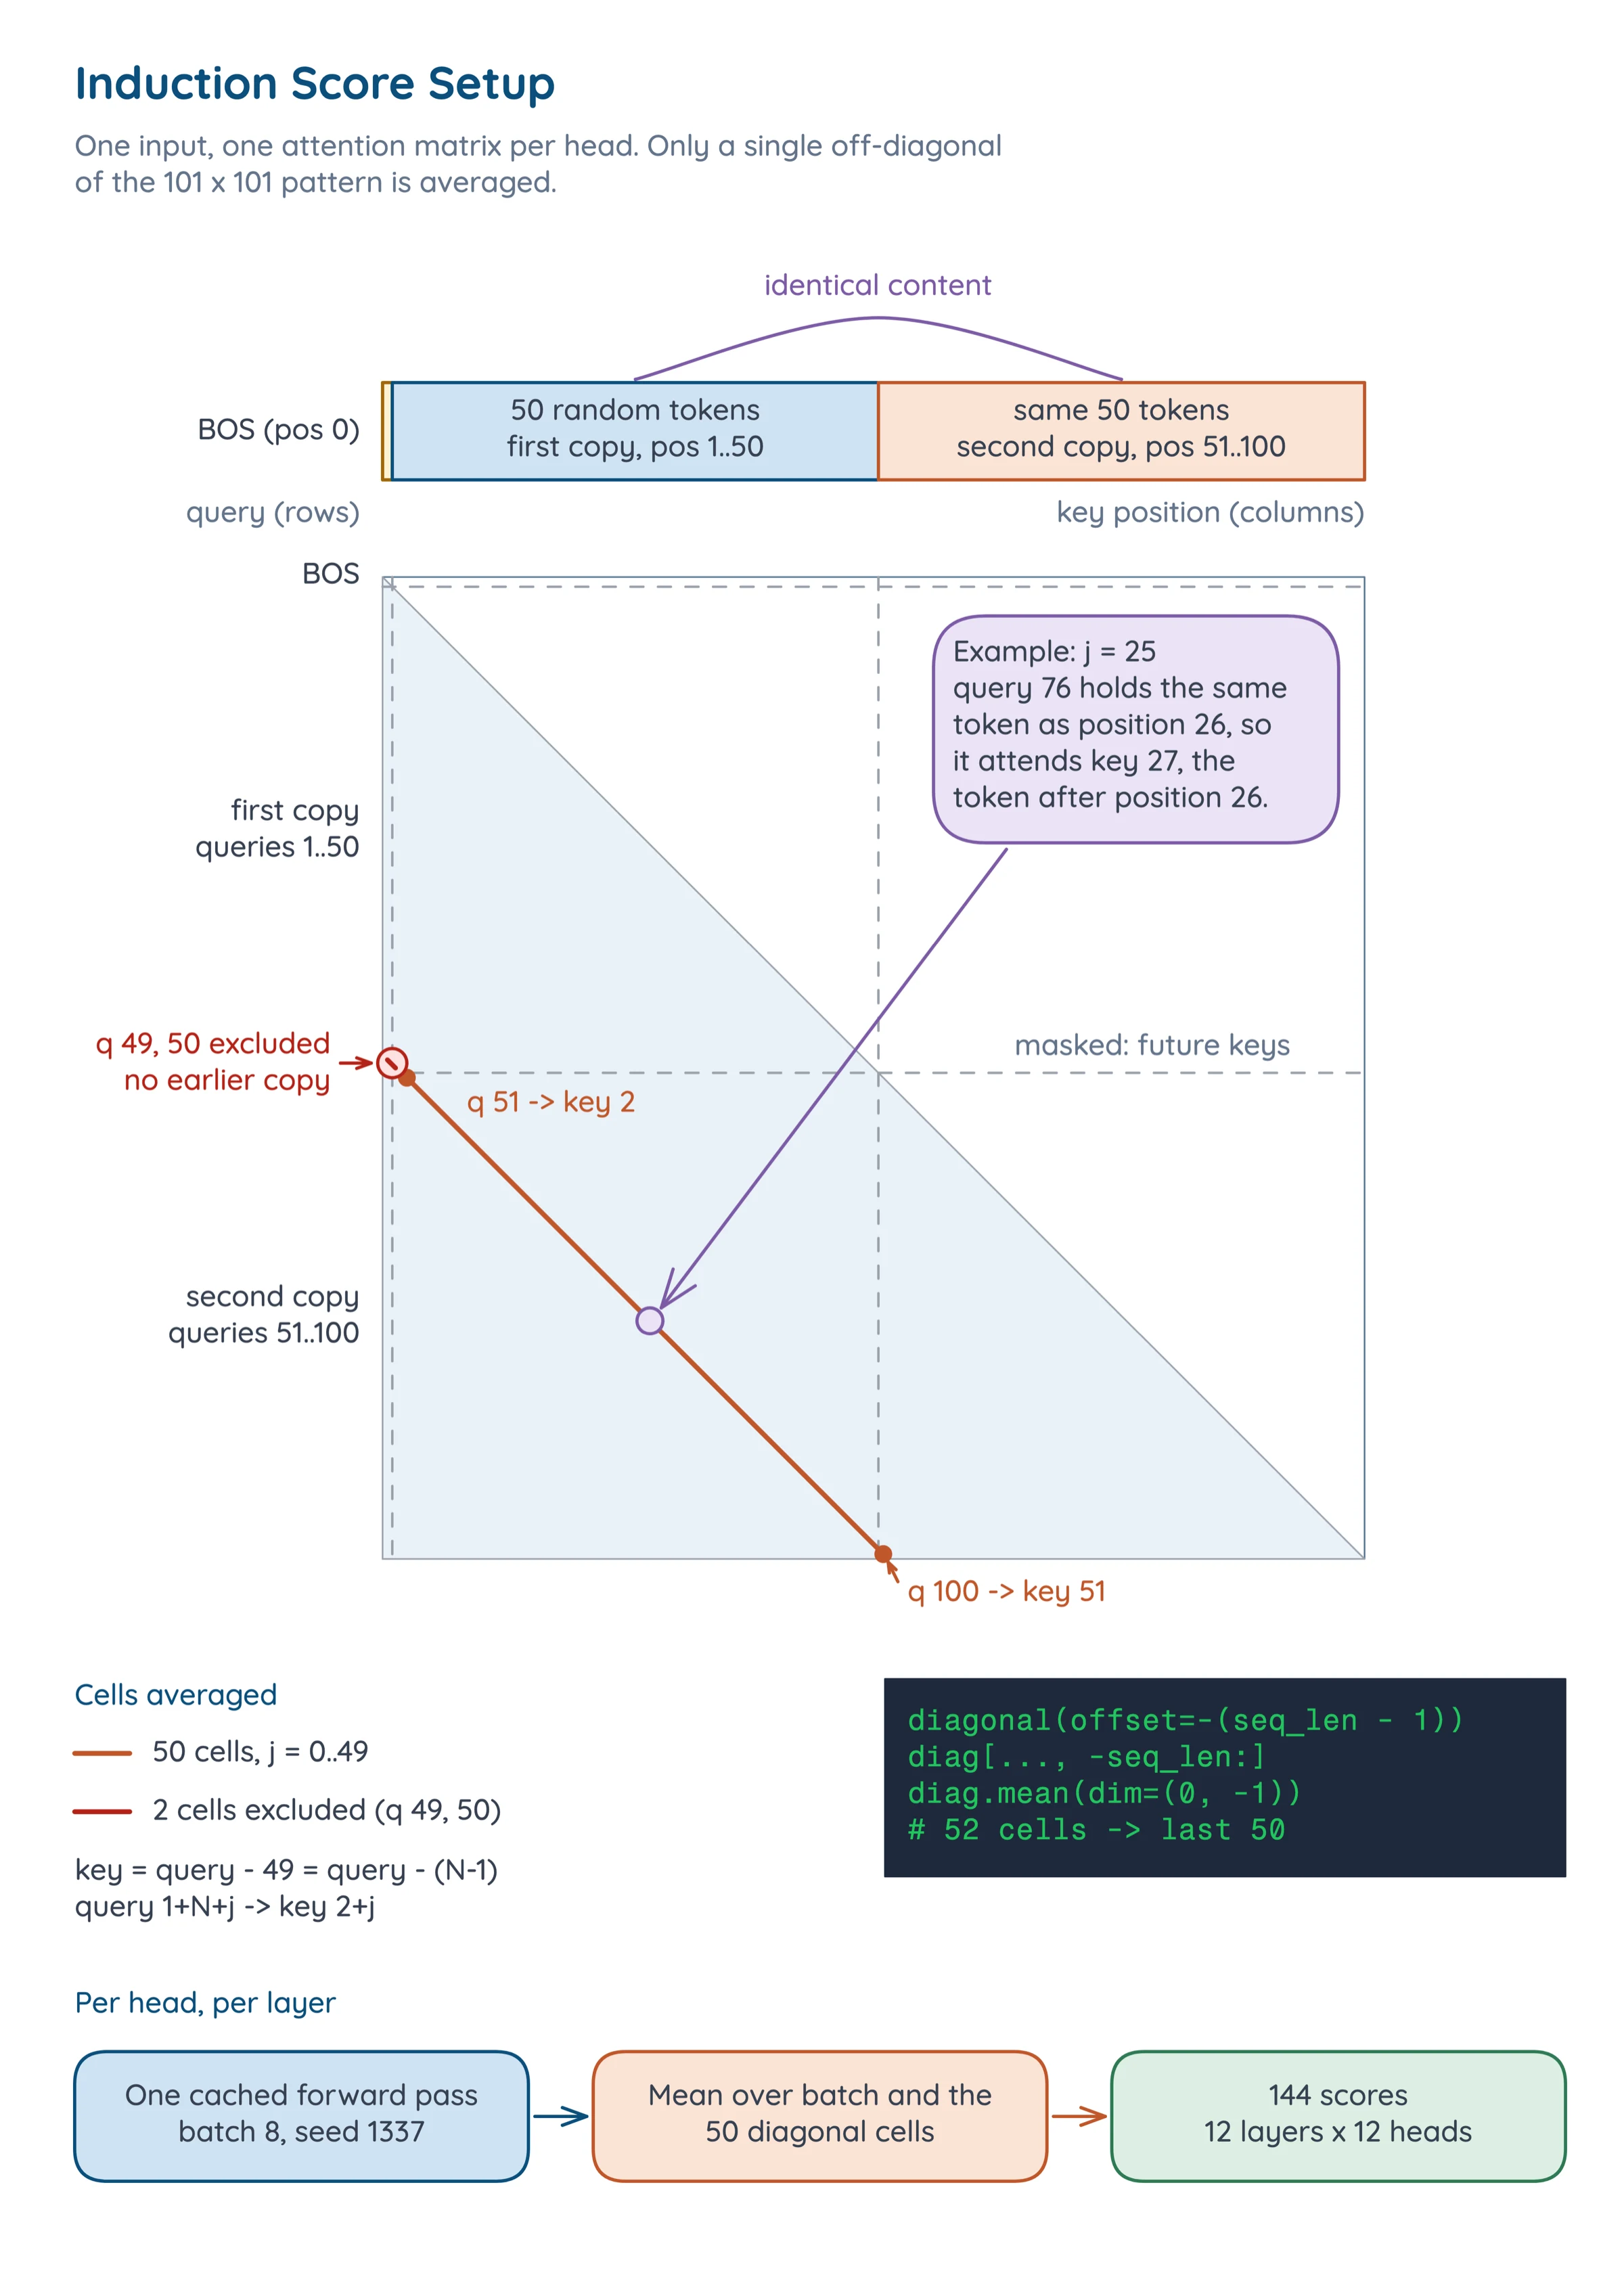
[BOS][50 random tokens][the same 50 tokens]. There is no grammar, no semantics, and no n-gram statistics worth exploiting. The only structure available is that the second half repeats the first, so a head scoring highly here cannot be scoring highly for a reason we failed to think of.
This is the load-bearing design decision in the experiment. It buys a clean reading. The score means one thing. It costs external validity. Every conclusion below is about behavior on inputs GPT-2 never saw in training, and a head specialized for this diagonal on random tokens is not yet shown to do anything on English.
The Induction Score
Under that construction, a head doing induction at position
For a head with attention weights
Query
Implementation
The configuration is sequence length 50, batch 8, seed 1337, one cached forward pass, 144 numbers out.
pattern = cache["pattern", layer] # [batch, head, query, key] |
What TransformerLens Changes About the Model Before You Measure It
TransformerLens loads GPT-2 with LayerNorm folding, centered writing weights, and centered unembedding on by default. These change the parameterization without changing the function the model computes, and they are what make residual-stream and logit-lens [11] analysis clean. A score computed on an unprocessed model is not being compared against the same object the published results describe.
This is why reproducing a known result was the point of experiment 01 rather than a formality. L5H5 and L6H9 are in the literature [1]; we did not find them, we recovered them, with our own metric implementation, our own input construction, and our own weight processing. A pipeline that recovers the canonical heads from scratch is a pipeline that can be pointed at questions with no answer key. That validation step is usually invisible in the write-up, and it is the step that decides whether any later number means anything.
Results
| Head | Induction score |
|---|---|
| L5H5 | 0.925 |
| L6H9 | 0.915 |
| L7H10 | 0.905 |
| L5H1 | 0.902 |
| L7H2 | 0.820 |
| L10H1 | 0.529 |
| L9H6 | 0.509 |
| L9H9 | 0.500 |
| L10H7 | 0.459 |
| L5H0 | 0.436 |
We do not report an interval on these scores. With a single seed and a batch of 8, the run supports the ranking and the size of the rank-5 to rank-6 gap; it does not support the third decimal place. The per-head scores are stable across seeds in informal checks, but a seed sweep is a ten-line change that has not been run, so that stability is an impression rather than a measurement. Read the table as an ordering.
Correction, September 26, 2026. An earlier version averaged the diagonal over two extra first-half query positions, which have no earlier copy to look back to. That diluted every score by about 2% and put L5H1 above L7H10. The five-head set and the size of the gap did not change. The formula above also had an off-by-one in the key index, now fixed; the code was already correct on that point.
What the Gap Means
Attention is a probability distribution over the entire 101-token context. A score of 0.925 means L5H5 places about 92% of its attention mass on a single position, and that position is determined purely by a structural rule in an input with no content to attend to. This is not a tendency toward induction. It is a head that does one job.
Five heads sit above 0.80 and the sixth sits at 0.53. The 0.290 gap between rank 5 and rank 6 is the reason the set is well defined. No threshold has to be chosen, because the data separates. Had the scores decayed smoothly from 0.9 to 0.4, "the induction heads" would name whatever cutoff we picked, and every downstream experiment would inherit that arbitrariness.
The second feature of the table is location. The five heads sit in layers 5 through 7 of a 12-layer model, downstream of the layer-0 previous-token heads the circuit needs as input, with enough depth remaining to influence the output. The theory predicts where these heads should live, and that is where they are. A prediction that could have failed and did not is worth more than the scores themselves, because the scores were always going to be high for something.
What I Would Change
What the Ranking Does Not Establish
Everything above is consistent with the five heads being passengers. A head can attend to exactly the right position for an unrelated reason while some other component performs the copy, and no attention-pattern measurement can tell the difference. Four objections remain open.
| Objection | Experiment | Method |
|---|---|---|
| Correlation, not causation | 03 | Activation patching [7][8], clean vs. corrupted repeated sequences |
| Composition is assumed, not shown | 04 | Path patching [1][9] on the prev-token → induction edge |
| The behavior may be input-specific | 05 | Eigenvalues and diagonal dominance of |
| Other heads may be redundant backups | 06 | Zero and mean ablation, head knockout sweep |
The distinction between 03 and 05 is the one that matters most. Activation patching is a statement about this model on these inputs; showing that the OV circuit is approximately a copy matrix is a statement about the parameters, independent of whatever inputs we happened to construct. Input-level evidence and weight-level evidence fail in different ways, and a circuit claim is only strong when both hold.
Experiment 06 is the one most likely to produce an awkward result. Ablation studies in this literature routinely find that knocking out a "necessary" component degrades behavior far less than the discovery evidence suggests, because other heads absorb the loss [1][10]. If that happens here it is a finding about the circuit rather than a defect in the measurement, but it would complicate the clean two-head story considerably. We would rather name that possibility now than after the fact.
The Remaining Five Experiments
The plan, with the evidence each step is meant to produce.
| Experiment | Question | Evidence it produces |
|---|---|---|
| 02 | Does the attention pattern look the way the score implies? | Per-head attention visualization on the repeated sequence |
| 03 | Do these heads cause the copying? | Recovery of logit difference under activation patching |
| 04 | Is the prev-token → induction edge real? | Path patching isolating that specific edge |
| 05 | Is the OV circuit a copy matrix? | Spectrum and diagonal dominance of |
| 06 | Are the heads necessary? | Behavior collapse under zero and mean ablation |
Only 02 is a refinement of what is already measured. Experiments 03 through 06 are the ones that can overturn the reading above, and none of them has been run.
Conclusions
Had we stopped at the score table, this post would have told a circuit-discovery story. Recovering L5H5 and L6H9 with an independent implementation is a validated instrument reading and nothing more. It establishes that the measurement is correct on a case with a published answer, which is the precondition for trusting it anywhere else.
- The five-head set is sharply defined. The 0.290 gap between rank 5 and rank 6 is in the data, not in a chosen threshold.
- The heads sit in layers 5 through 7, where the composition story says they must. That prediction could have failed.
- Nothing here separates "these heads participate in induction" from "these heads cause induction." Patching and ablation separate them, and they are not run.
- The reported scores support an ordering, not three decimal places. No seed sweep has been run.
- Laptop-scale interpretability on a real pretrained model is genuinely accessible. The whole experiment is one cached forward pass over eight sequences of 101 tokens.
Find the code at github.com/SadeekFarhan21/projects.farhansadeek.com/tiny-circuits.
References
- Kevin Wang, Alexandre Variengien, Arthur Conmy, et al. Interpretability in the Wild: a Circuit for Indirect Object Identification in GPT-2 small. ICLR, 2023. arXiv:2211.00593
- Alec Radford, Jeffrey Wu, Rewon Child, et al. Language Models are Unsupervised Multitask Learners. OpenAI, 2019. link
- Neel Nanda, Joseph Bloom. TransformerLens. Software, 2022. link
- Catherine Olsson, Nelson Elhage, Neel Nanda, et al. In-context Learning and Induction Heads. Transformer Circuits Thread, 2022. arXiv:2209.11895
- Nelson Elhage, Neel Nanda, Catherine Olsson, et al. A Mathematical Framework for Transformer Circuits. Transformer Circuits Thread, 2021. link
- Ashish Vaswani, Noam Shazeer, Niki Parmar, et al. Attention Is All You Need. NeurIPS, 2017. arXiv:1706.03762
- Kevin Meng, David Bau, Alex Andonian, et al. Locating and Editing Factual Associations in GPT. NeurIPS, 2022. arXiv:2202.05262
- Stefan Heimersheim, Neel Nanda. How to use and interpret activation patching. arXiv preprint, 2024. arXiv:2404.15255
- Nicholas Goldowsky-Dill, Chris MacLeod, Lucas Sato, et al. Localizing Model Behavior with Path Patching. arXiv preprint, 2023. arXiv:2304.05969
- Thomas McGrath, Matthew Rahtz, Janos Kramar, et al. The Hydra Effect: Emergent Self-repair in Language Model Computations. arXiv preprint, 2023. arXiv:2307.15771
- nostalgebraist. interpreting GPT: the logit lens. LessWrong, 2020. link