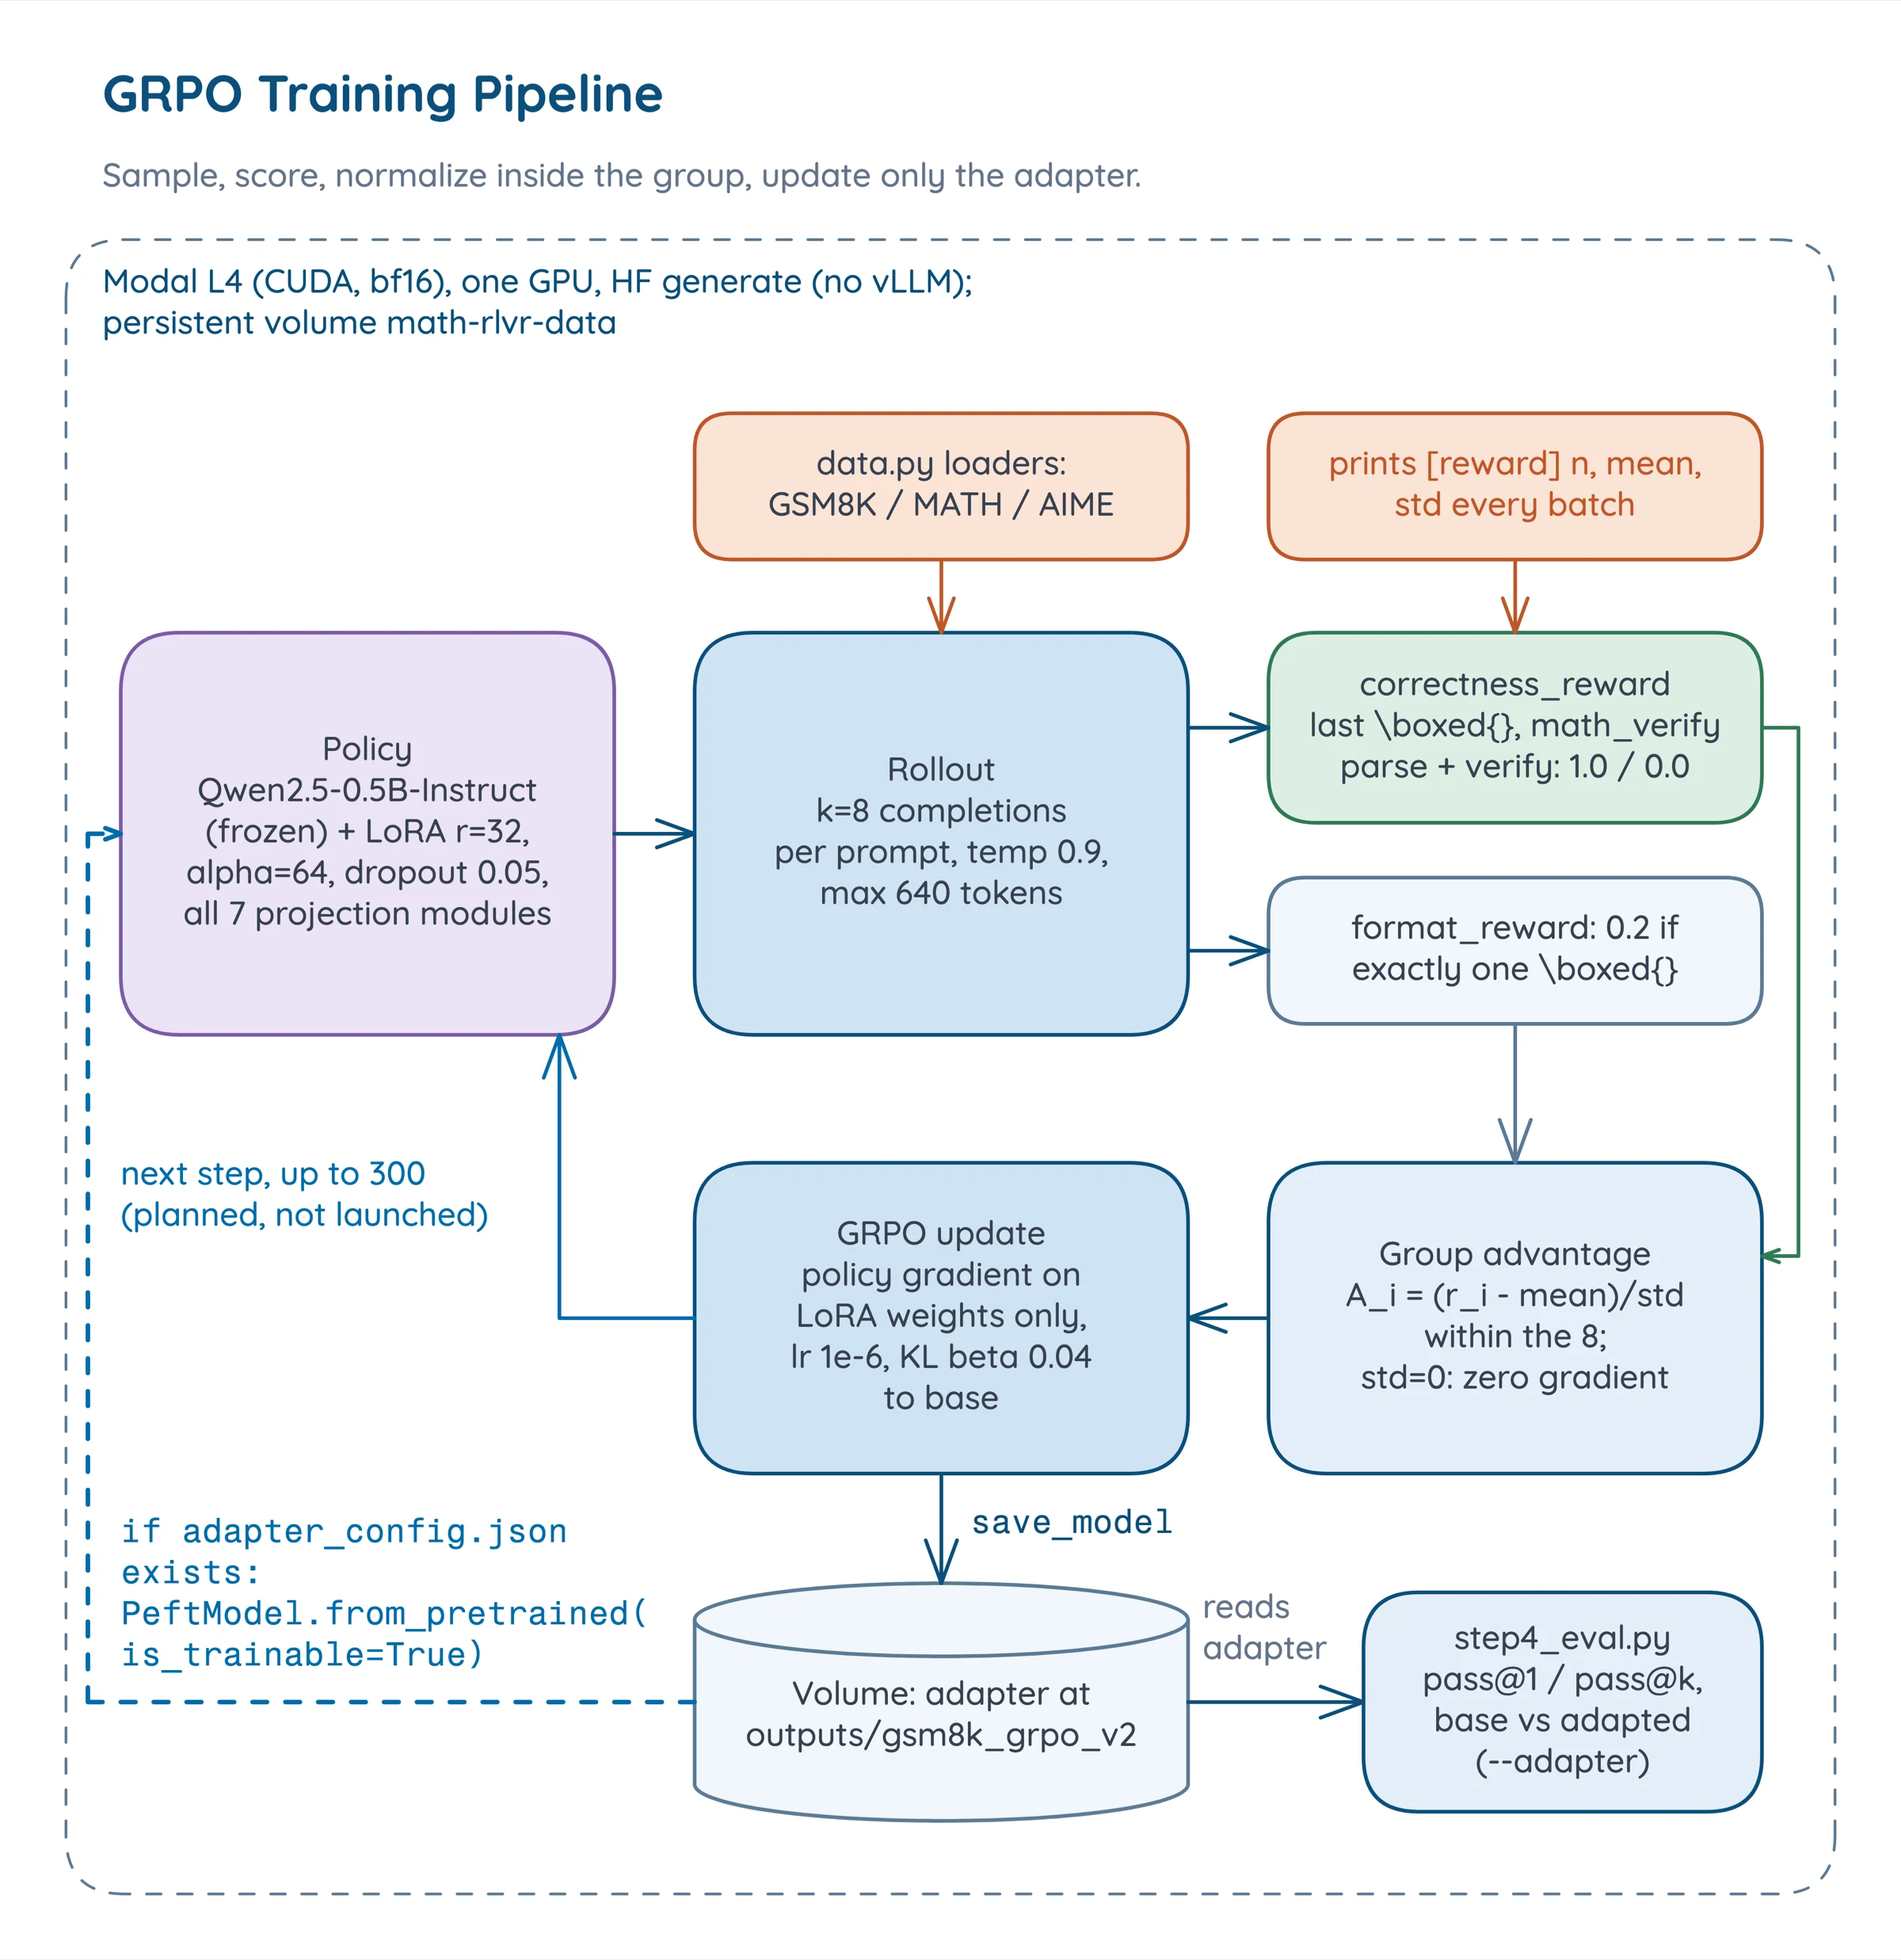
This RLVR pipeline produced a diagnosis and four post-mortems. The diagnosis is that the learning signal in GRPO [1] is the within-group spread of rewards rather than their level, which makes "my dataset is too easy" and "my dataset is too hard" indistinguishable from outside the reward function. The post-mortems cover four engineering failures (a token-id collision, non-terminating rollouts, generation running in train mode, and a silently frozen adapter), none of which raised an exception, and all of which produced a training run that looked healthy.
We also measured hardware instead of assuming it. For this workload a rented Modal L4 ran about 5% faster per step than an M4 Pro laptop, because per-step time is dominated by serial decode overhead rather than arithmetic. That is one paired observation, not a benchmark.
Reading note. The argument is the variance diagnostic and why the four bugs share a shape.
Why It Matters
Reinforcement learning from verifiable rewards [2] is the cleanest setup in post-training. There is no reward model to train, no human preference data, and no judge model to be gamed. A math problem has a right answer, a program checks it, and the check is the reward. It is the recipe behind the reasoning-model results of the last two years [3], and at 500M it fits on one GPU.
That cleanliness is also what makes the failure modes legible. When the only moving parts are sample, score, and update, anything that goes wrong is in one of three places, which is why this project is worth writing up even without a training curve.
Technical Details
The setup is GRPO via TRL 0.16 [4] on Qwen2.5-0.5B-Instruct [5], LoRA [6] (math_verify [7] as the reward, 8 generations per prompt, learning rate
GRPO, and Where the Signal Comes From
For each prompt, sample a group of
The policy is then pushed toward the above-average members of its own group. There is no value network and no critic to train. The group average is the baseline. That is the entire simplification, and at this scale it is the reason to use GRPO rather than PPO [8].
Read the numerator once more, because the dominant failure mode falls directly out of it. If every completion in a group receives the same reward, then
The condition for learning is therefore
Zero within-group variance arrives from both directions, and the two are indistinguishable downstream.
| Training set | What happens | Reward std | Learning signal |
|---|---|---|---|
| GSM8K [9] | The Instruct model aces the problem 8/8 | None | |
| AIME | 90 olympiad problems, 0/8 on nearly all | None | |
| MATH [10] levels 3–5 | Sometimes right, sometimes wrong | Yes |
"Too easy" and "too hard" produce the identical symptom. Flat reward, no movement, and a run that otherwise looks completely healthy. Wall-clock burns, the loss curve is plausible, and nothing improves. Any diagnosis that only asks whether reward is increasing cannot separate them, and the two have opposite fixes.
The Verifier Is Part of the Objective
The other half of RLVR is deciding whether a completion's answer matches the gold answer. Completions are prompted to end in \boxed{...}, so extraction is a regex on the last match. Comparison is where the subtlety lives.
String Equality vs. Symbolic Comparison
| Model's boxed answer | Gold | String equality | math_verify |
|---|---|---|---|
72 |
72 |
correct | correct |
0.5 |
1/2 |
wrong | correct |
\frac{1}{2} |
1/2 |
wrong | correct |
40 |
72 |
wrong | wrong |
(no \boxed{}) |
72 |
none | wrong |
Rows two and three are the reason this matters. A naive string check produces a biased reward. It systematically punishes correct answers for being written in a different form, and therefore trains the model toward the dataset's formatting conventions rather than toward being right. Parsing both sides symbolically and checking mathematical equality is the only version that rewards the intended thing.
Stated generally, the verifier is the objective. Every systematic error in it becomes a systematic pressure on the policy.
Implementation
The Diagnostic
So the reward function prints its own variance on every batch.
n = len(rewards) |
Ten lines of arithmetic that convert a silent failure into a visible one. It is the single most useful thing in the pipeline. The general form is that the learning signal in policy-gradient RL comes from the spread of outcomes, not their level. That makes curriculum design a precondition here.
Training Configuration
| Parameter | Value |
|---|---|
| Base model | Qwen2.5-0.5B-Instruct |
| Adapter | LoRA, |
| Generations per prompt ( |
8 |
| Learning rate | |
| KL coefficient ( |
0.04 |
| Sampling temperature | 0.9 |
| Max completion length | 640 tokens |
| Correctness reward | 1.0 if math_verify accepts, else 0.0 |
| Format shaping | 0.2 for exactly one well-formed \boxed{} |
| Planned horizon | 300 steps (not launched) |
The format shaping term exists so that early in training there is a gradient toward parseable output before there is any gradient toward correctness. It is deliberately small relative to the correctness reward, so it cannot dominate once completions parse.
Problems
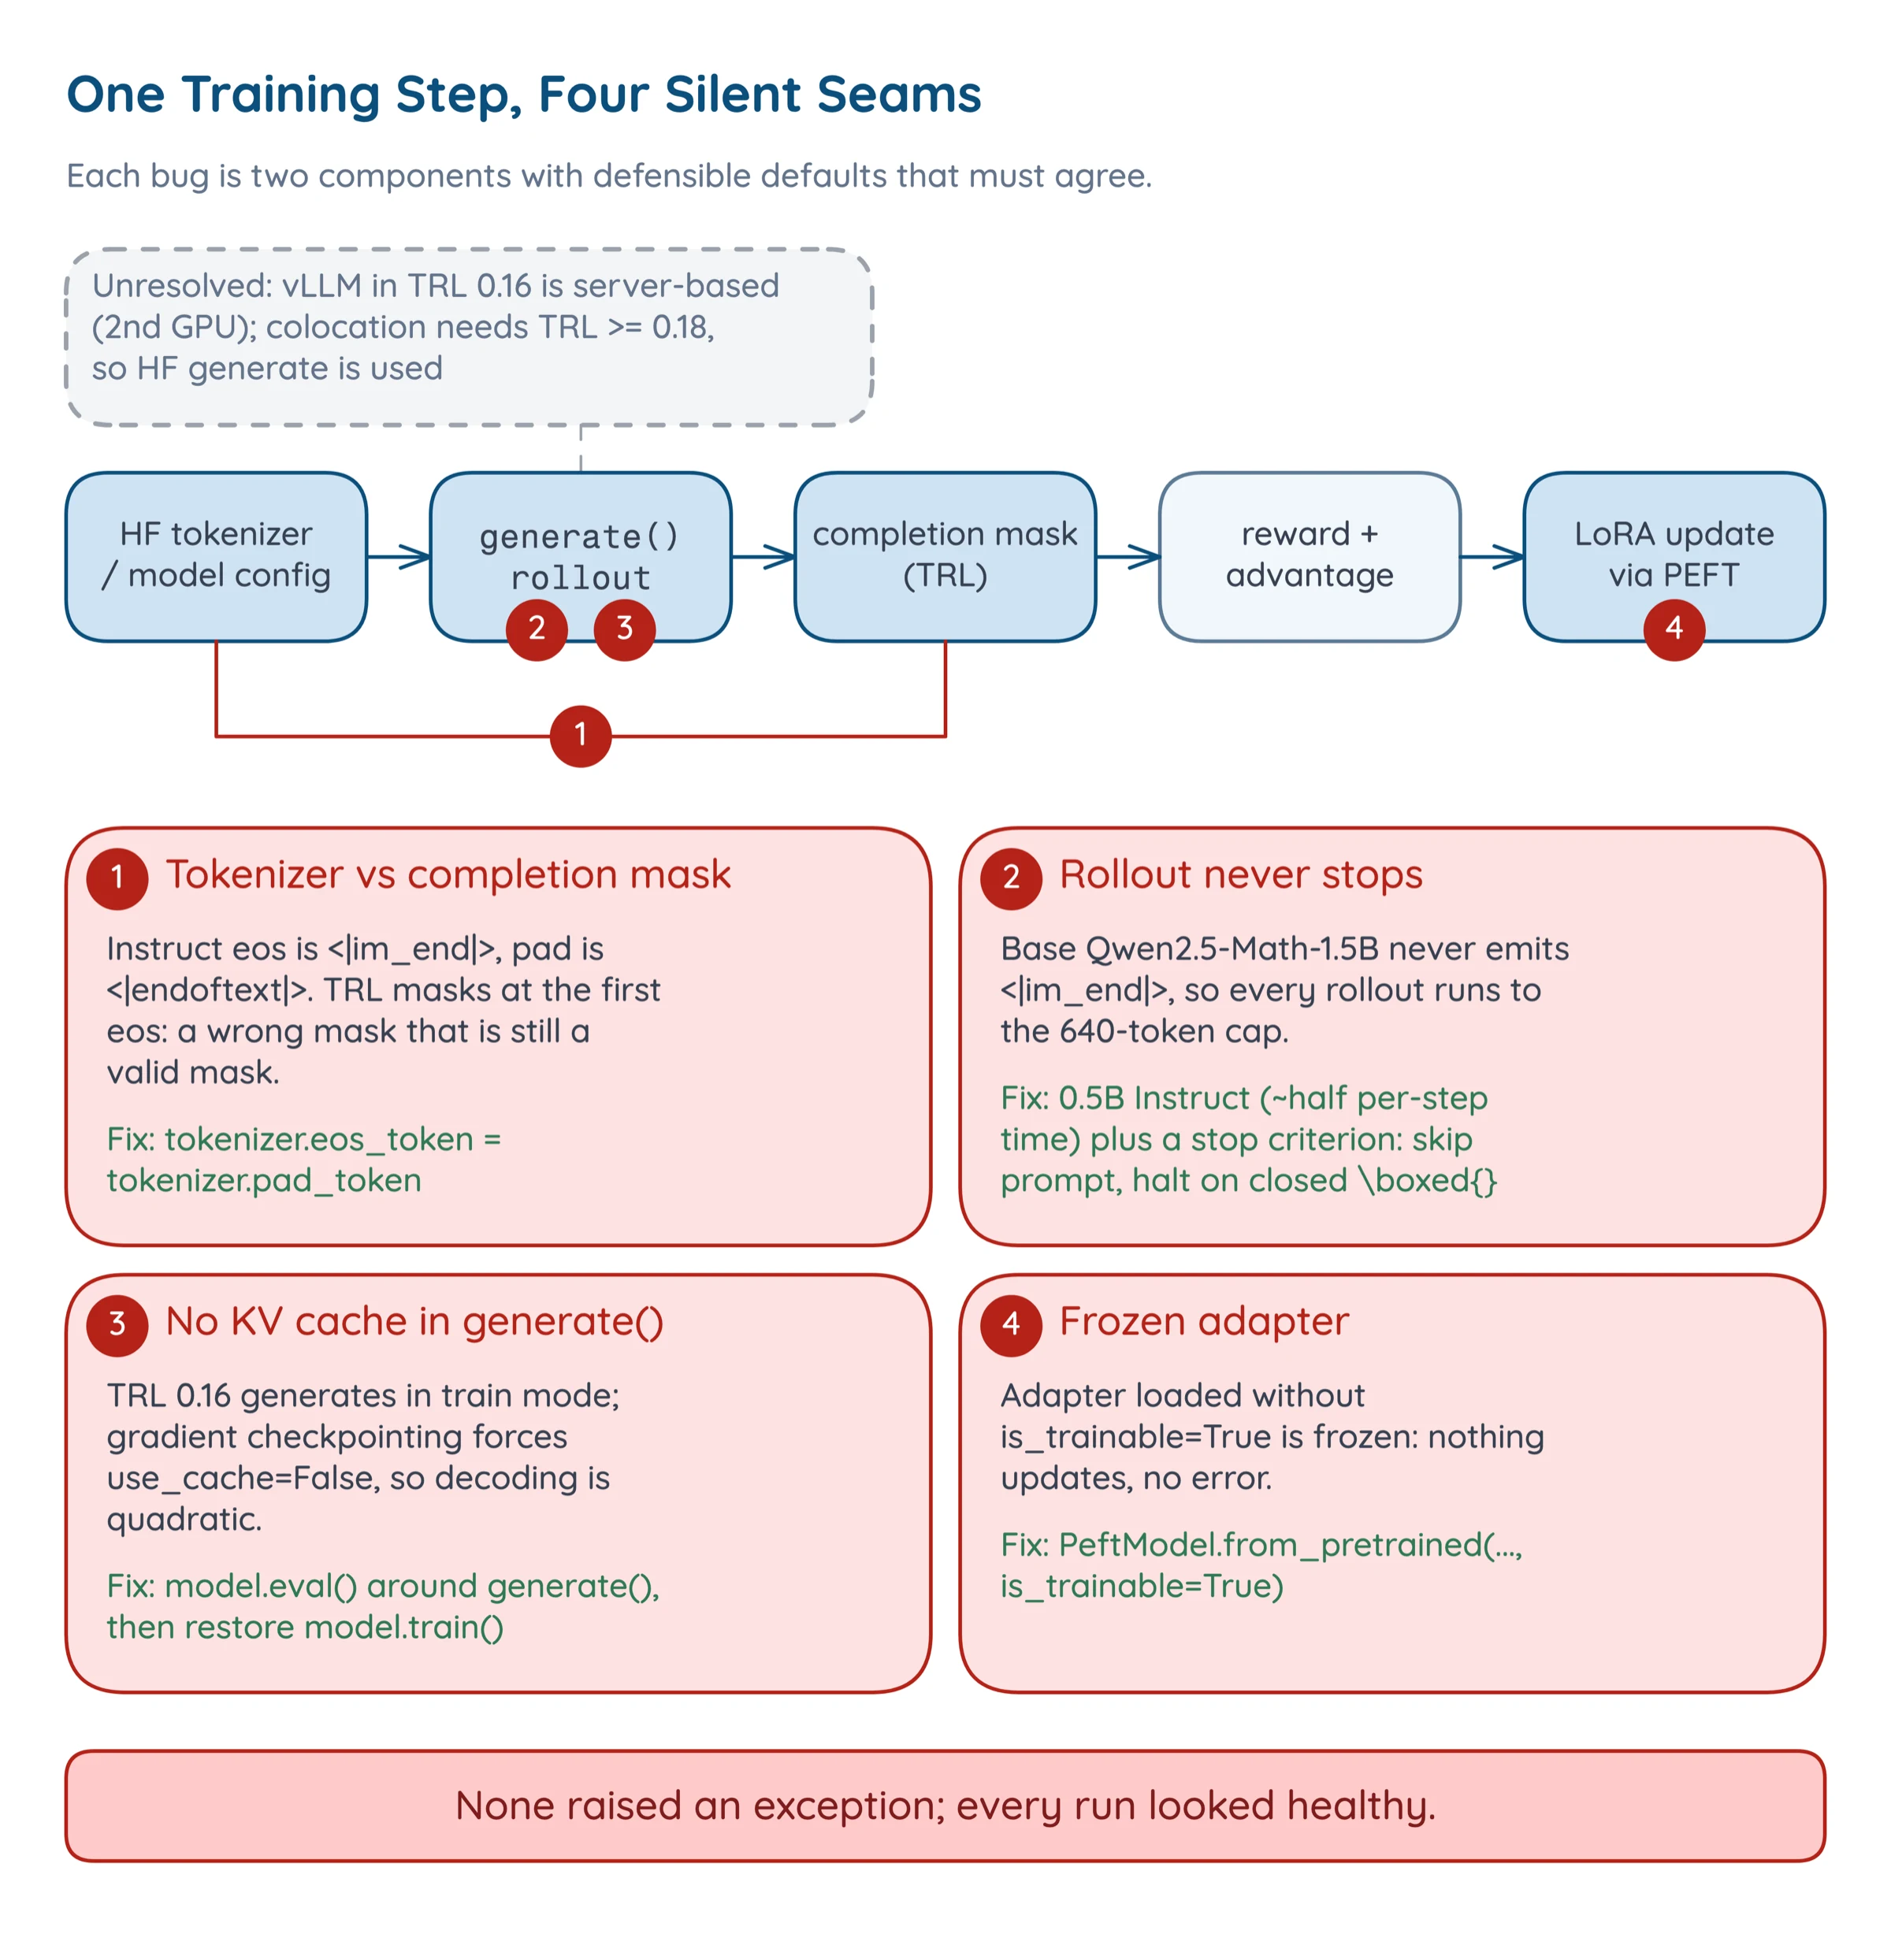
None of these raised an exception. All four produced a training run that appeared to work. They share one shape. Two components with defensible independent defaults must agree, and don't. That is the most common category of bug we hit in this project.
1. The EOS/Pad Collision
Instruct models set eos_token to <|im_end|>. HuggingFace Transformers [11] pads stopped rollouts with pad_token. TRL masks each completion at the first eos. If those two tokens disagree, the completion mask is wrong, and nothing tells you, because a wrong mask is still a valid mask.
tokenizer = AutoTokenizer.from_pretrained(MODEL, padding_side="left") |
One line, several hours of diagnosis.
2. Rollouts That Never Terminate
We started on the Qwen2.5-Math-1.5B [12] base model. Its chat tokens are untrained, so it never emits <|im_end|> at all, so every rollout ran to the completion-length cap. At 8 generations per prompt and 640 tokens each, nearly all of the compute was spent generating text after the answer had already been given.
Two fixes followed: switching to the 500M Instruct model, which also roughly halved per-step time, and adding a stopping criterion that halts a rollout as soon as it contains a closed \boxed{}.
class _StopAfterBoxed(StoppingCriteria): |
The prompt itself mentions \boxed{}, so the criterion has to skip the prompt prefix, the kind of detail that turns a clean idea into a debugging session.
3. Generation Running in Train Mode
TRL 0.16 calls generate() without switching the model to eval. With gradient checkpointing enabled, that forces use_cache=False. No KV cache means decoding is quadratic in sequence length rather than linear, on the single most expensive part of the step.
was_training = model.training |
A large speedup for a small patch, and again not something that surfaces as an error. It surfaces as "training is slower than I expected," which is indistinguishable from "training is this slow."
4. The Adapter That Loaded Frozen
If an adapter already exists at the output directory, the trainer loads it through PEFT [13] with is_trainable=True and continues, rather than starting a fresh LoRA.
model = PeftModel.from_pretrained(base, args.output_dir, is_trainable=True) |
Omitting is_trainable loads the adapter frozen. Training then updates nothing, reports no error, and produces a complete run with a plausible log.
A fifth issue is unresolved rather than fixed. TRL 0.16's vLLM [14] integration is server-based and wants a second GPU, and single-GPU colocation requires TRL 0.18 or later. The runs therefore use HuggingFace generate on one L4 and accept the throughput. That decision is what the next section measures.
Experiments
The Hardware Measurement
| Setup | Time per step |
|---|---|
| M4 Pro laptop (MPS) | ~77 s |
| Modal L4 (CUDA, bf16) | ~73 s |
The rented datacenter GPU was roughly 5% faster than the laptop. At 300 steps that is about 6 to 6.5 hours either way.
This is a single paired observation (one configuration, one run on each device, no repetitions), so it carries no interval and should not be read as a benchmark. What it does support is a directional claim with a mechanism behind it. Per-step time is dominated by generation overhead in HuggingFace generate, not by matrix multiplication. Sampling 8 completions of up to 640 tokens is a long serial sequence of small, latency-bound decode steps, and a wider GPU does not shorten a serial loop.
The consequences follow from the mechanism rather than from the 5%. Larger GPUs cost proportionally more per hour for roughly the same wall-clock, and a T4 is a false economy because it lacks bf16 and loses more time than it saves in price. The real fix is batched inference through vLLM, continuous batching [15] and paged attention [14], which is blocked on the TRL version above.
Results
What Exists
We have no before/after RL numbers. The pipeline runs end to end, the 300-step training run has not been launched, and we are publishing before it deliberately. Nothing below is contingent on what the final
| Component | State |
|---|---|
| Data loaders (GSM8K, MATH, AIME → prompt/answer pairs) | Done |
| Verifier and reward-variance diagnostic | Done |
| GRPO training with LoRA, adapter-resume across runs | Done |
| Done | |
| Modal deployment, persistent volume, wandb | Done |
| 300-step training run | Not launched |
| Before/after results | None |
Conclusions
The stack is built but not yet tested against its own objective, and everything of value so far came out of it refusing to work.
- Reward variance is the metric to watch, not reward mean. Printing
every batch is ten lines and converts the most likely failure from invisible to obvious. - Too-easy and too-hard are the same observation from outside. Any diagnosis that checks only whether reward is increasing cannot separate them, and they have opposite fixes.
- The verifier is the objective. A string-equality check is a biased reward function, not an approximate one.
- Every failure here was silent. EOS/pad mismatch, non-terminating rollouts, generation in train mode, a frozen adapter. Four bugs, zero exceptions.
- Measure before renting. For this workload the GPU bought about 5%, on one paired observation, because the bottleneck is serial decode rather than arithmetic.
- The difficulty band is unmeasured. Levels 3–5 produce nonzero variance; we have not swept difficulty against
, so the curriculum is a working choice rather than a tuned one.
The open question is whether 300 steps on a 500M model moves
Find the code at github.com/SadeekFarhan21/projects.farhansadeek.com/math-rlvr.
What I Would Change
The claim above is that MATH levels 3–5 produce nonzero within-group variance and the alternatives did not. That is an observation from the diagnostic, not a characterization of the difficulty band.
We did not measure where the band actually sits for this model. The principled version sweeps difficulty against measured
That sweep has not been run, so "levels 3–5" is a working choice supported by a binary observation, not a tuned curriculum. It is the first thing we would run given more time, and it is cheap relative to training.
References
- Zhihong Shao, Peiyi Wang, Qihao Zhu, et al. DeepSeekMath: Pushing the Limits of Mathematical Reasoning in Open Language Models. arXiv preprint, 2024. arXiv:2402.03300
- Nathan Lambert, Jacob Morrison, Valentina Pyatkin, et al. Tulu 3: Pushing Frontiers in Open Language Model Post-Training. COLM, 2025. arXiv:2411.15124
- DeepSeek-AI, Daya Guo, Dejian Yang, et al. DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning. Nature, 2025. arXiv:2501.12948
- Leandro von Werra, Younes Belkada, Lewis Tunstall, et al. TRL: Transformers Reinforcement Learning. Hugging Face, 2020. link
- Qwen: An Yang, Baosong Yang, Beichen Zhang, et al. Qwen2.5 Technical Report. arXiv preprint, 2024. arXiv:2412.15115
- Edward J. Hu, Yelong Shen, Phillip Wallis, et al. LoRA: Low-Rank Adaptation of Large Language Models. ICLR, 2022. arXiv:2106.09685
- Hynek Kydlíček. Math-Verify: Math Verification Library. Hugging Face, 2025. link
- John Schulman, Filip Wolski, Prafulla Dhariwal, et al. Proximal Policy Optimization Algorithms. arXiv preprint, 2017. arXiv:1707.06347
- Karl Cobbe, Vineet Kosaraju, Mohammad Bavarian, et al. Training Verifiers to Solve Math Word Problems. arXiv preprint, 2021. arXiv:2110.14168
- Dan Hendrycks, Collin Burns, Saurav Kadavath, et al. Measuring Mathematical Problem Solving With the MATH Dataset. NeurIPS Datasets and Benchmarks, 2021. arXiv:2103.03874
- Thomas Wolf, Lysandre Debut, Victor Sanh, et al. Transformers: State-of-the-Art Natural Language Processing. EMNLP System Demonstrations, 2020. doi:10.18653/v1/2020.emnlp-demos.6
- An Yang, Beichen Zhang, Binyuan Hui, et al. Qwen2.5-Math Technical Report: Toward Mathematical Expert Model via Self-Improvement. arXiv preprint, 2024. arXiv:2409.12122
- Sourab Mangrulkar, Sylvain Gugger, Lysandre Debut, et al. PEFT: State-of-the-art Parameter-Efficient Fine-Tuning methods. Hugging Face, 2022. link
- Woosuk Kwon, Zhuohan Li, Siyuan Zhuang, et al. Efficient Memory Management for Large Language Model Serving with PagedAttention. SOSP, 2023. arXiv:2309.06180
- Gyeong-In Yu, Joo Seong Jeong, Geon-Woo Kim, et al. Orca: A Distributed Serving System for Transformer-Based Generative Models. OSDI, 2022. link
- Yang Yue, Zhiqi Chen, Rui Lu, et al. Does Reinforcement Learning Really Incentivize Reasoning Capacity in LLMs Beyond the Base Model? NeurIPS, 2025. arXiv:2504.13837
- Mark Chen, Jerry Tworek, Heewoo Jun, et al. Evaluating Large Language Models Trained on Code. arXiv preprint, 2021. arXiv:2107.03374